How to Build an Automated Blog Content Pipeline for SaaS (That Runs Without You)
Most SaaS founders are running a content operation that looks less like a pipeline and more like a pile — half-published drafts, stale keyword lists, and a blog that hasn't shipped anything in three weeks because someone had to 'find time' to write. Sound familiar? You're not understaffed. You're under-engineered.
In 2026, the SaaS companies compounding organic growth aren't hiring bigger content teams — they're building systems. An automated blog content pipeline turns keyword discovery, content generation, publishing, and optimization into a closed loop that runs on logic, not labor [1]. The playbook exists. The tools exist. The only thing missing is the architecture.
This guide breaks down exactly how to build an automated blog content pipeline for SaaS — from data inputs to publish triggers — so your content operation scales without headcount, and your blog becomes an asset that works while you ship product.
What Is an Automated Blog Content Pipeline (and Why SaaS Needs One)
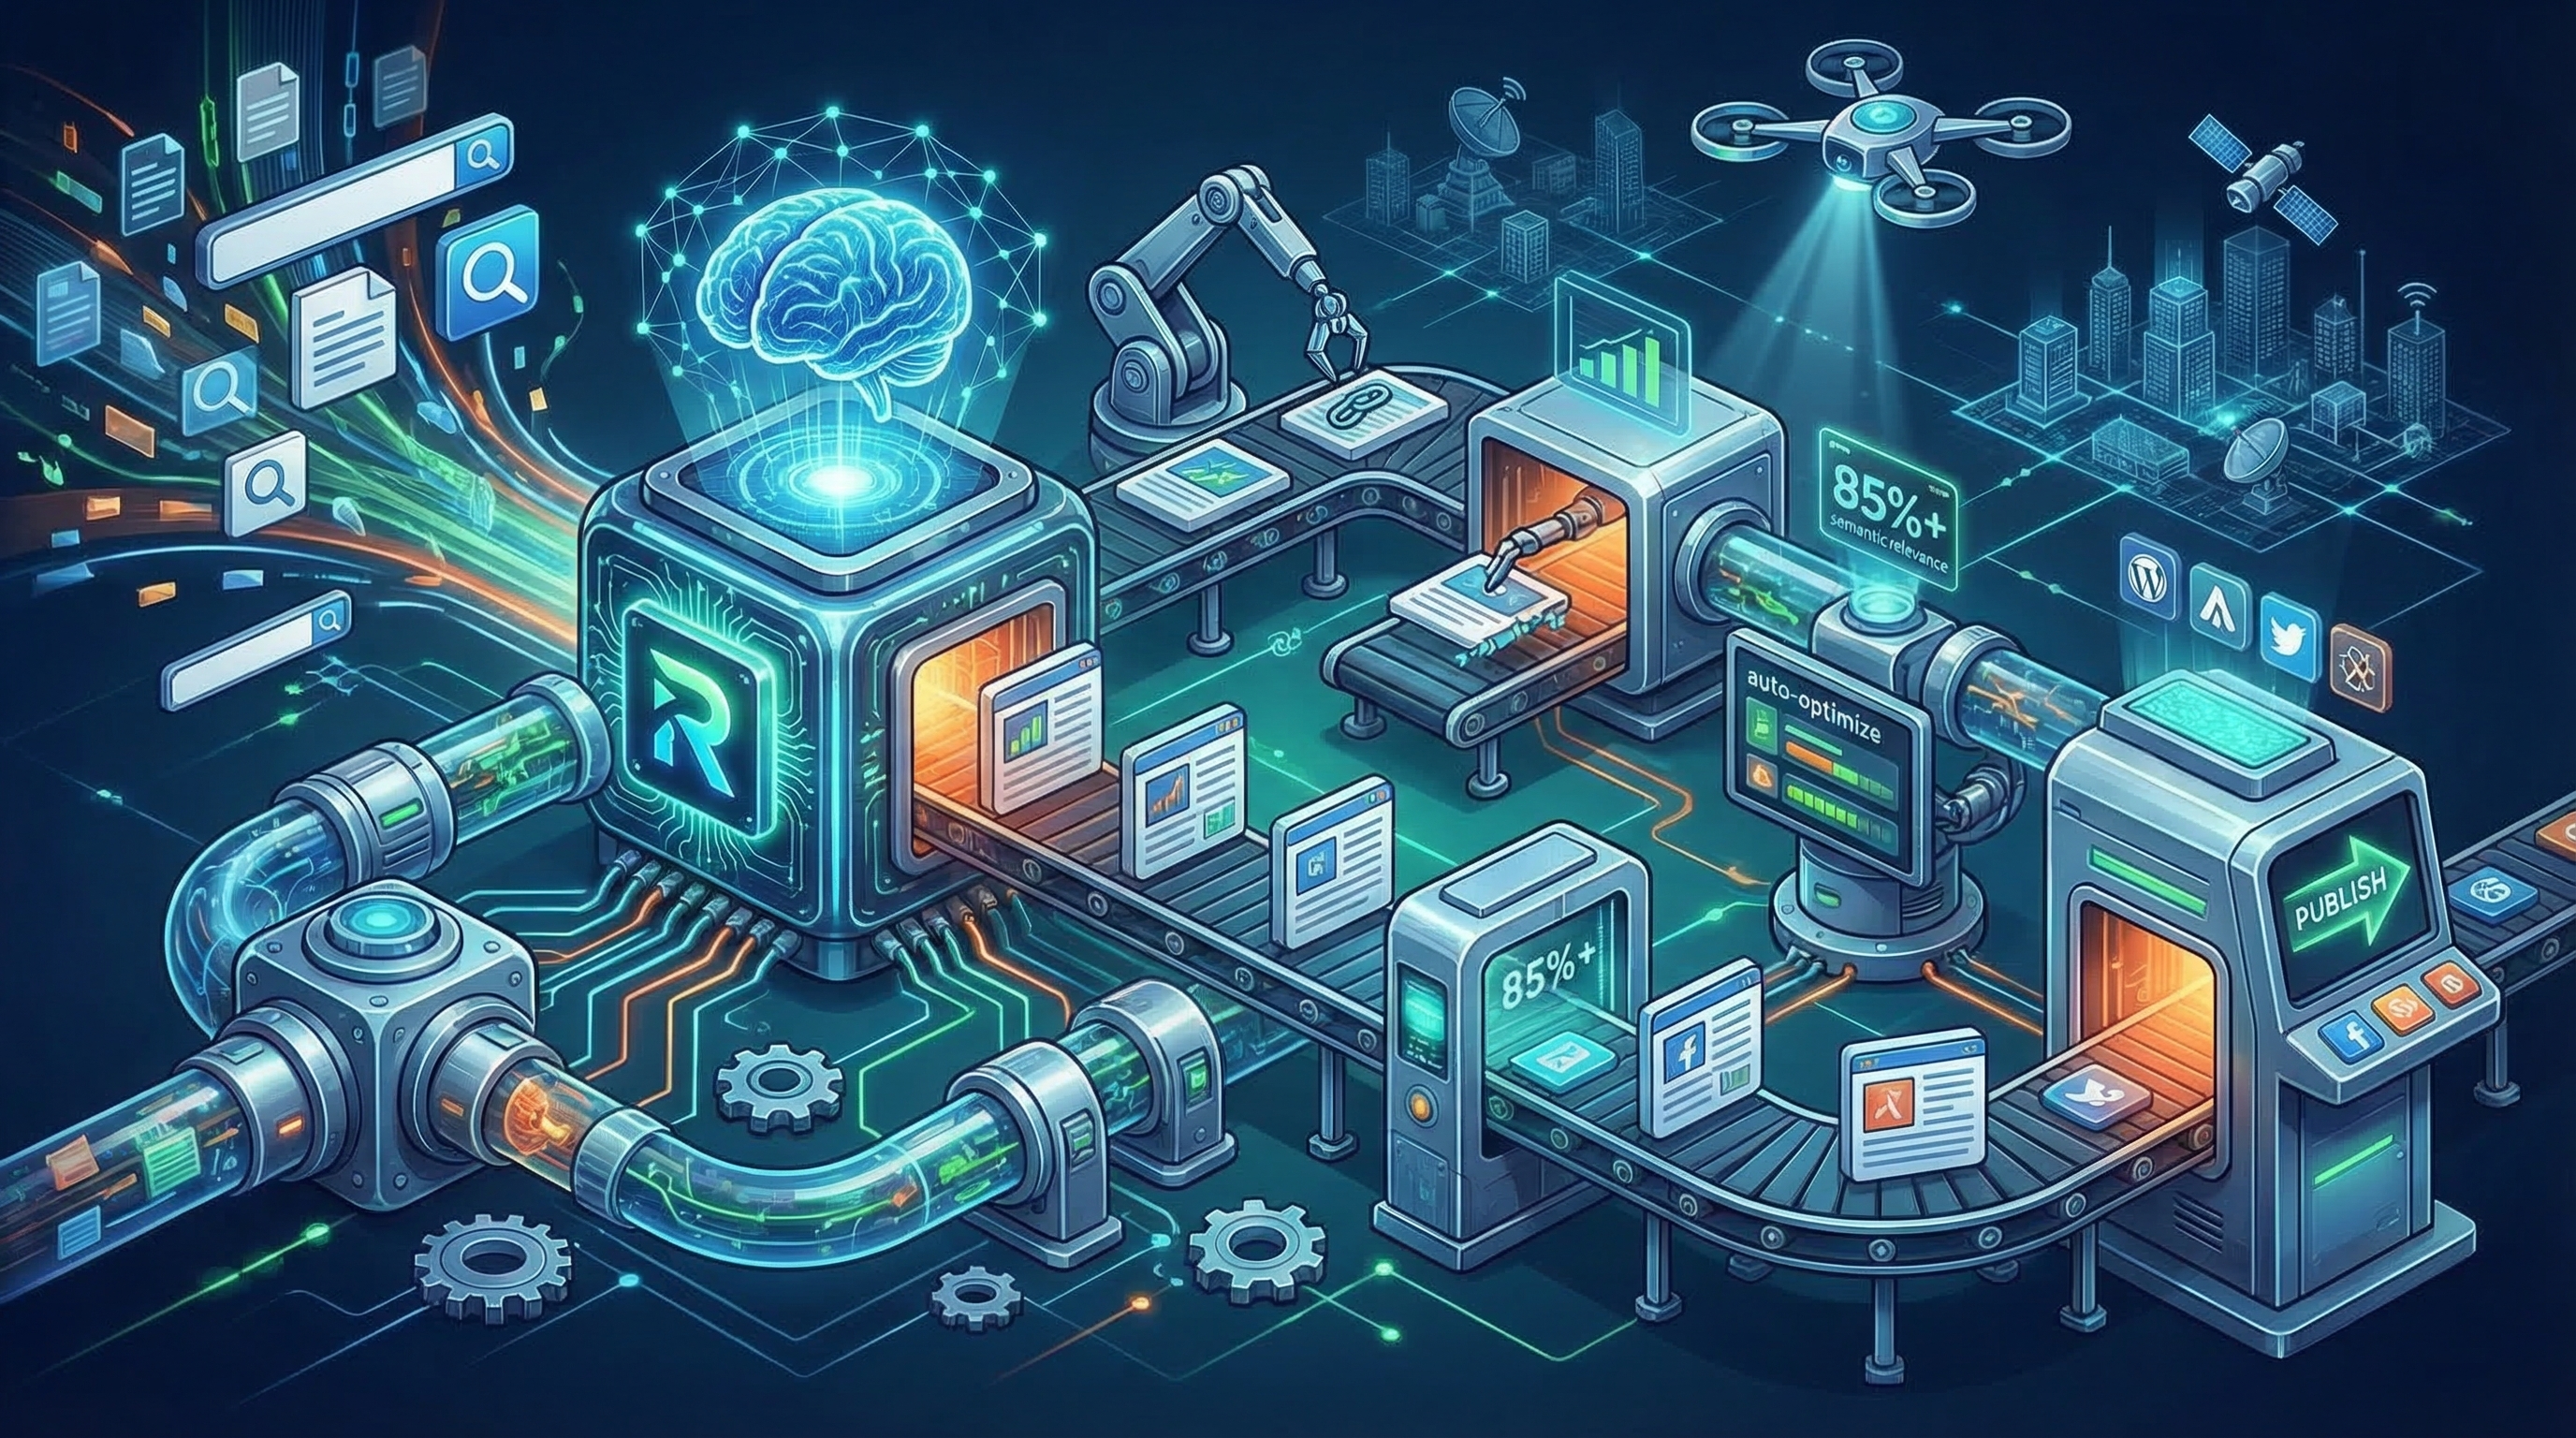
An automated blog content pipeline is a closed-loop system: keyword intake flows into brief generation, brief generation feeds content creation, content creation triggers publishing, publishing enters performance monitoring, and monitoring fires refresh triggers when rankings slip. Every stage hands data to the next. No human has to relay the baton.
Contrast that with the manual alternative: one-off articles commissioned from freelancers, agency retainers that bill by the word, and ad-hoc publishing schedules that exist only on someone's mental calendar. Manual content operations aren't strategies — they're reactions.
SaaS is uniquely positioned to benefit from pipeline automation. The keyword surface area is enormous: product features, use cases, integrations, comparisons, alternatives, changelogs. The content need is recurring and predictable. And the SEO returns compound — each published, optimized article adds domain authority that makes the next article rank faster [2]. The math is unambiguous: a pipeline that publishes 20 articles per month at scale doesn't just outpace a team shipping 4 — it geometrically outcompetes it over 12 months.
Pipeline vs. Workflow: The Difference That Changes Everything
A workflow is linear and human-dependent. Someone assigns a task, someone writes a brief, someone writes the draft, someone approves it, someone publishes it. The chain breaks every time a human is unavailable, distracted, or context-switching between client fires.
A pipeline is automated, self-triggering, and data-driven. It doesn't wait for an editorial calendar — it executes on conditions. When a keyword hits a volume threshold, the brief generates. When the draft clears QA gates, it publishes. When a ranking drops below a threshold, a refresh workflow fires.
Most SaaS content 'strategies' are actually just workflows wearing a pipeline's clothing. They have a Notion doc with a content calendar and a Slack channel with occasional updates. That's not a system — that's organized chaos.
The Cost of Not Automating in 2026
Agency retainers for content production in 2026 average $3,000–$8,000 per month for a lean SaaS engagement. Infrastructure for an automated pipeline — API access, AI generation, rank tracking — runs a fraction of that. The ROI math is brutal for manual ops.
Worse, content decay is accelerating. Articles that ranked in 2024 are dropping without active refresh signals [3]. Google's quality signals are more dynamic than they've ever been. A blog that publishes and forgets is a blog that loses ground quietly, month after month. Every hour your team spends on content operations is an hour not spent on product, GTM, or the ten other things that actually need a human.
The Core Components of a SaaS Content Pipeline
Strip away the tooling and every automated content pipeline has four engine layers: Discovery, Generation, Publishing, and Optimization. Each layer should be automated or semi-automated with clean data handoffs between stages. The pipeline is only as strong as its weakest handoff — broken data in means broken content out.
Layer 1 — Discovery: Turning Data Into a Keyword Queue
Discovery is the intake valve. It converts raw search data into a prioritized queue of content opportunities. Feed it Google Search Console exports, Ahrefs data pulls, or Semrush API outputs. These aren't manual research exercises — they're scheduled data pulls that run on their own.
Programmatic keyword clustering groups opportunities by intent, funnel stage, and topic authority. Automate prioritization logic: search volume × difficulty × conversion proximity = publish order. High-intent, low-competition keywords that sit closest to your conversion funnel publish first. Everything else queues behind them.
Tools that feed the discovery layer include the GSC API, SEMrush API, and custom Python scripts that cluster semantically related keywords and score them against domain authority benchmarks. This is infrastructure, not research.
Layer 2 — Generation: Brief-to-Draft Without a Writer in the Loop
Generation is where most SaaS founders start — and where most pipelines stop. AI writing tools are table stakes. What separates a real generation layer from a ChatGPT session is structured input engineering [2].
Automatic brief construction pulls from the keyword cluster data: competitor gap analysis surfaces which headings to cover, SERP scraping identifies content depth requirements, and target word counts are set by what's already ranking. The brief is a data schema, not a document.
Prompt engineering matters more than the model. Structured inputs produce structured outputs. Brand voice rules — your ICP language, positioning assertions, terminology standards — are encoded at the prompt level, not patched in during editing. The result is drafts that sound like your brand without a human editor in the loop.
Quality gates run before anything touches the CMS: SEO score checks, internal linking opportunity flags, readability scores, and factual structure reviews. Edge cases get flagged for human review. Everything else advances automatically.
Layer 3 — Publishing: Automated CMS Deployment
The copy-paste bottleneck is where pipelines die in most SaaS operations. Someone generates the content, and then it sits in a Google Doc waiting for someone to format it, upload it, add metadata, and hit publish. That's not a pipeline — that's a relay race with no second runner.
CMS integrations eliminate this entirely. WordPress REST API, Webflow CMS API, and Ghost's Admin API all support programmatic content deployment. Metadata generates automatically: title tags, meta descriptions, slug structures, and schema markup are computed from the keyword data, not written by hand.
Internal linking automation is non-negotiable at this layer. Content published without links into your existing topic graph is dead weight. Programmatic link injection identifies contextually relevant anchor opportunities in the new draft and in existing content, then wires them at publish time.
Scheduling logic governs publish cadence: crawl budget, site authority, and content velocity targets determine how many articles deploy per week, not whoever has time to press publish.
Layer 4 — Optimization: The Loop That Keeps Rankings Alive
A pipeline that only publishes is half a system. The optimization layer is what separates a content factory from a compounding asset [SOURCE_5].
Automated performance monitoring tracks rankings for every published URL. When positions drop below a defined threshold, refresh workflows trigger automatically — pulling updated SERP data, identifying content gaps, and queuing a re-optimization pass. Google Search Console data feeds back into the loop: impressions-to-clicks gaps surface semantic coverage holes that can be filled without publishing new pages.
This is the difference between a pipeline that publishes and a pipeline that compounds. Month 6 performance isn't just the sum of six months of articles — it's the result of six months of active optimization running in the background.
Building the Pipeline: The 2026 SaaS Playbook
Here's the architecture walkthrough for a solo founder or lean SEO team. This isn't about stacking tools — it's about wiring a system where each component feeds the next.
Step 1 — Map Your Keyword Universe by Funnel Stage
TOFU content (informational: how-to, what-is, best-of) builds awareness and domain authority. MOFU content (commercial: comparisons, alternatives, use cases) captures evaluation-stage buyers. BOFU content (transactional: integration pages, feature landing pages, pricing comparisons) converts.
Automate funnel-stage tagging using intent classifiers or keyword modifier rules. Keywords containing 'how to' or 'what is' auto-tag as TOFU. Keywords containing 'vs', 'alternative', or 'best' auto-tag as MOFU. Keywords containing your product name, feature names, or 'pricing' auto-tag as BOFU. The queue populates itself.
Step 2 — Build Your Content Brief Template as a Data Schema
Stop treating briefs as documents. A brief is structured data that feeds generation. Build it as a JSON schema or spreadsheet template with required fields: target keyword, secondary keywords, funnel stage, competitor URLs, target H2 structure, word count, and CTA directive.
Populate brief fields automatically using SERP scraping APIs and competitor analysis tools. The H2 structure comes from clustering the headings that appear across top-10 ranking pages for your target keyword. Word count targets are set by the median length of ranking content. This is systematic, not subjective.
Step 3 — Configure Your Generation and QA Layer
Choose generation infrastructure based on your quality bar and volume requirements: GPT-4o, Claude 3.5, or fine-tuned models with brand-specific training data all work — the model matters less than the prompt architecture surrounding it.
Build prompt templates that encode your ICP, voice rules, and structural requirements as system-level instructions, not ad-hoc requests. Your automated QA checklist should score each draft on SEO signal coverage, readability grade level, internal link density, and heading structure before it advances to publish. Human-in-the-loop flags can catch edge cases without blocking the full pipeline throughput.
Step 4 — Wire Publishing and Monitoring Into a Single Feedback Loop
Every URL that publishes should auto-enter a rank monitoring queue from day one. Connect CMS deployment to your rank tracker via API. Set performance thresholds — if a page drops more than five positions in 30 days, it enters the refresh queue automatically.
Build a single dashboard that shows pipeline throughput (articles queued, drafted, published), ranking velocity (new rankings acquired per week), and content ROI (organic traffic delta by cohort). This is your system's control panel, not a reporting exercise.
Tools and Stack for an Automated SaaS Content Pipeline
Evaluate tools by their API access, data output quality, and integration flexibility — not their feature marketing. The orchestration layer is the glue that makes everything else work.
The Lean Stack for Solo SaaS Founders
Minimal viable pipeline: GSC data pull → keyword scoring script → AI generation via API → CMS deployment via REST API → rank tracker monitoring. Monthly infrastructure cost should sit well below a single agency retainer month.
Prioritize minimizing manual touchpoints over maximizing feature count. The best stack for a solo founder is the one that runs the longest without anyone touching it. If you're looking to move fast, see how Ranklynk runs this entire pipeline end-to-end without stitching together five separate tools.
The Scale Stack for Agencies and Content-Heavy SaaS
Multi-site pipeline management requires one orchestration layer — Make, n8n, or custom infrastructure — with multiple CMS targets. Role-based access and approval gates serve client-facing pipelines where a human checkpoint is contractually required. Reporting automation generates client performance reports directly from pipeline data, eliminating the weekly reporting grind entirely.
Common Failure Modes (And How to Engineer Around Them)
Most automated pipelines fail at the handoff points, not the generation layer. Generic output is a prompt engineering problem. Publishing without monitoring is a feedback loop with no signal. Here's how to engineer around the three most common failure modes.
Failure Mode 1 — No Keyword Prioritization Logic
Publishing random keywords in random order produces random results. Without prioritization logic, pipelines burn generation capacity on low-value targets while high-conversion opportunities sit in the queue. Build a scoring model that weights conversion proximity heavily, deprioritizes high-competition terms until domain authority justifies them, and revisits scoring logic quarterly as your site's competitive position shifts.
Failure Mode 2 — Static Prompts That Produce Static Output
SERPs change. Competitor content densifies. Format preferences shift. Static prompts that worked in Q1 produce outdated output by Q3. Treat prompts like code: version them, test variants against ranking outcomes, and update them on a defined cadence. A/B testing prompt structures against ranking data — not just readability — is how pipelines stay competitive over time [3].
Failure Mode 3 — The Orphaned Content Problem
Content published without internal links is dead weight. It can't accumulate PageRank. It doesn't contribute to topical authority. It just sits there. Automate internal linking at publish time using a content graph model that maps your existing URL inventory by topic and keyword cluster. Run retroactive audits on existing content to surface link gaps. Treat your blog as an interconnected system, not a list of URLs.
What a Fully Autonomous SaaS Content Pipeline Looks Like in Practice
Here's the trigger chain in production: A keyword cluster hits volume and competition thresholds → brief auto-generates from SERP data → draft produces via the generation layer → QA gates pass → article deploys to CMS with metadata and internal links → URL enters rank monitoring queue → 45 days later, ranking drops from position 8 to position 14 → refresh workflow fires → updated draft with gap-filled content re-deploys → ranking recovers to position 6.
No writer assigned. No editor pinged. No Slack message asking 'who owns this one?'
The compounding curve is the story. Month 1, you have 20 articles in the index. Month 6, you have 120 articles — with the first 20 now refreshed and climbing. Month 12, you have a content asset with domain authority that took competitors three years to build manually. That's what 'SEO that runs itself' actually means in production [1].
When to Build vs. When to Buy a Pre-Built Pipeline
Building gives you control. Buying gives you speed. Most SaaS founders need speed first — they need organic traffic compounding while they're still finding product-market fit, not after they've hired a three-person engineering team to maintain a custom pipeline.
Evaluate pre-built solutions on autonomy depth: does it just generate content, or does it also publish, monitor, and refresh? A tool that only handles generation is a word processor with better UX. The real cost of building is engineering time, maintenance overhead, and iteration cycles — all of which compound against you when your actual job is building the product [SOURCE_5].
What to look for in a turnkey automated content pipeline: closed-loop architecture from discovery to refresh, native CMS integrations, GSC data connectivity, and performance-triggered optimization workflows. If a solution doesn't close the loop, it's not a pipeline — it's a drafting tool.
The Bottom Line
An automated blog content pipeline isn't a content strategy upgrade — it's an infrastructure decision. SaaS companies that build closed-loop systems in 2026 will compound organic traffic while their competitors are still scheduling editorial meetings and hunting down freelancers.
The pipeline layers are clear: discovery feeds generation, generation feeds publishing, publishing feeds monitoring, and monitoring feeds itself. Every manual step you eliminate is a compounding return you unlock. Every article that auto-refreshes when rankings slip is traffic you didn't have to manually fight for.
The founders who stopped babysitting their content didn't get lucky — they got systematic. The architecture is here. The only question is whether you build it or buy it. If you want to skip the build entirely, see how Ranklynk handles keyword discovery, content generation, automated publishing, and performance-triggered refresh as a single closed-loop system — no writer, editor, or SEO manager required.
Frequently Asked Questions
Q: What is an automated blog content pipeline for SaaS?
An automated blog content pipeline for SaaS is a closed-loop system that connects every stage of content production — from keyword discovery to publishing and performance monitoring — without requiring manual handoffs between stages. In a true pipeline, keyword intake flows into brief generation, which feeds content creation, which triggers publishing, which enters performance tracking, and which fires refresh workflows when rankings slip. Unlike a traditional content workflow that depends on humans relaying tasks, an automated pipeline executes on data-driven conditions. For example, when a keyword hits a volume threshold, a brief is automatically generated; when a draft clears QA gates, it publishes without manual approval. SaaS companies benefit especially from this approach because their keyword surface area is large and predictable — covering product features, integrations, comparisons, and use cases — making the recurring content need a perfect fit for systematic automation.
Q: How is a content pipeline different from a content workflow for SaaS blogs?
The key difference is human dependency. A content workflow is linear and breaks whenever a person is unavailable, distracted, or context-switching. Someone assigns the task, someone writes the brief, someone drafts it, someone approves it, and someone publishes it. Every link in that chain is a potential bottleneck. A content pipeline, by contrast, is self-triggering and data-driven. It doesn't wait for an editorial meeting or a Slack message — it executes automatically when predefined conditions are met. Many SaaS companies believe they have a pipeline when they actually have a workflow dressed up with a Notion content calendar and a Slack channel. That's organized chaos, not a system. A genuine automated blog content pipeline for SaaS operates on logic, not labor, and scales output without adding headcount.
Q: Why do SaaS companies specifically need an automated blog content pipeline?
SaaS companies are uniquely positioned to benefit from pipeline automation for several reasons. First, the keyword surface area is enormous and predictable — product features, use cases, integrations, competitor comparisons, and changelog updates all represent recurring, addressable content opportunities. Second, SEO returns in SaaS compound over time: each published and optimized article increases domain authority, which makes subsequent articles rank faster. A pipeline publishing 20 articles per month doesn't just outpace a team shipping 4 — it geometrically outcompetes it over 12 months. Third, content decay is accelerating in 2026, meaning articles that ranked two years ago are now losing ground without active refresh signals. Manual operations can't keep up with the refresh cadence required. An automated pipeline handles discovery, creation, publishing, and refreshing in a closed loop, giving SaaS companies a durable organic growth engine.
Q: What does it cost to build an automated blog content pipeline compared to a content agency?
The cost difference is significant. In 2026, agency retainers for SaaS content production average between $3,000 and $8,000 per month for a lean engagement. In contrast, the infrastructure required for an automated blog content pipeline — including API access, AI content generation tools, and rank tracking software — runs at a fraction of that cost. Beyond the direct savings, automation provides a structural advantage: a pipeline scales output without scaling headcount, meaning the cost per article drops as volume increases. With a manual agency model, cost scales linearly with output. The ROI math increasingly favors building a system over renting labor, especially for SaaS companies looking to compound organic growth over a 12-to-24-month horizon rather than pay for one-off content campaigns.
Q: What are the core components every automated SaaS content pipeline needs?
While the article outlines four engine layers in detail, every effective automated blog content pipeline for SaaS requires at minimum: a keyword discovery and intake layer that identifies and prioritizes content opportunities based on volume, competition, and business relevance; a brief generation layer that translates keyword data into structured content outlines; a content creation layer powered by AI generation with QA gates to ensure quality before publishing; a publish trigger layer that automates the final distribution step; and a performance monitoring layer that tracks rankings and fires refresh workflows when content begins to decay. Each layer passes data to the next, creating a true closed loop. Without all five stages connected, the pipeline becomes a partial workflow — and partial automation still breaks when humans need to relay the baton between disconnected stages.
Q: What is content decay and how does an automated pipeline address it?
Content decay refers to the gradual loss of search rankings that published articles experience over time without active optimization or updates. In 2026, Google's quality signals are more dynamic than ever, meaning content that ranked well in 2024 can quietly lose ground month after month if left untouched. A blog that publishes and forgets is not a static asset — it's a depreciating one. An automated blog content pipeline for SaaS addresses content decay by incorporating performance monitoring directly into the pipeline loop. When a tracked article drops below a defined ranking threshold, the system automatically triggers a refresh workflow — updating the content, improving internal links, or adding new sections — without requiring a human to notice the drop and manually initiate a fix. This keeps the content library compounding rather than eroding.
Q: Is an automated blog content pipeline suitable for early-stage SaaS companies or just larger ones?
An automated blog content pipeline for SaaS is arguably more valuable for early-stage companies than for large ones, precisely because early-stage teams have the least capacity to spare. A five-person SaaS team cannot realistically dedicate meaningful engineering or marketing hours to a consistent content operation without a system doing the heavy lifting. Building a pipeline early means organic content starts compounding sooner, which directly impacts customer acquisition costs and long-term growth curves. The infrastructure costs are accessible — API access, AI tools, and rank trackers don't require enterprise budgets. The main investment is architectural: designing the pipeline correctly from the start. Early-stage SaaS founders who treat content as a system rather than a task gain a durable, scalable growth channel without hiring a full content team prematurely.
Q: What common mistakes do SaaS companies make when trying to automate their blog content?
The most common mistake is confusing a content calendar with a content pipeline. Many SaaS teams add automation tools to an existing manual workflow and call it a pipeline — but if humans are still required to relay tasks between stages, the system will still break under capacity pressure. Another mistake is automating content creation without automating performance monitoring, which means the company publishes at scale but has no mechanism for refreshing decaying content. A third mistake is building without QA gates, letting low-quality AI-generated content publish unchecked, which can harm domain authority rather than build it. Finally, many SaaS companies start with keyword lists that are too narrow — focusing only on bottom-of-funnel terms — and miss the compounding value of a broader, layered keyword strategy that covers features, use cases, comparisons, and integrations across the full funnel.
References
[1] https://virayo.com/blog/saas-content-marketing. virayo.com. https://virayo.com/blog/saas-content-marketing
[2] https://www.integrate.io/blog/data-pipelines-saas-industry/. integrate.io. https://www.integrate.io/blog/data-pipelines-saas-industry/
[3] https://www.trysight.ai/blog/automated-blog-posting-software. trysight.ai. https://www.trysight.ai/blog/automated-blog-posting-software