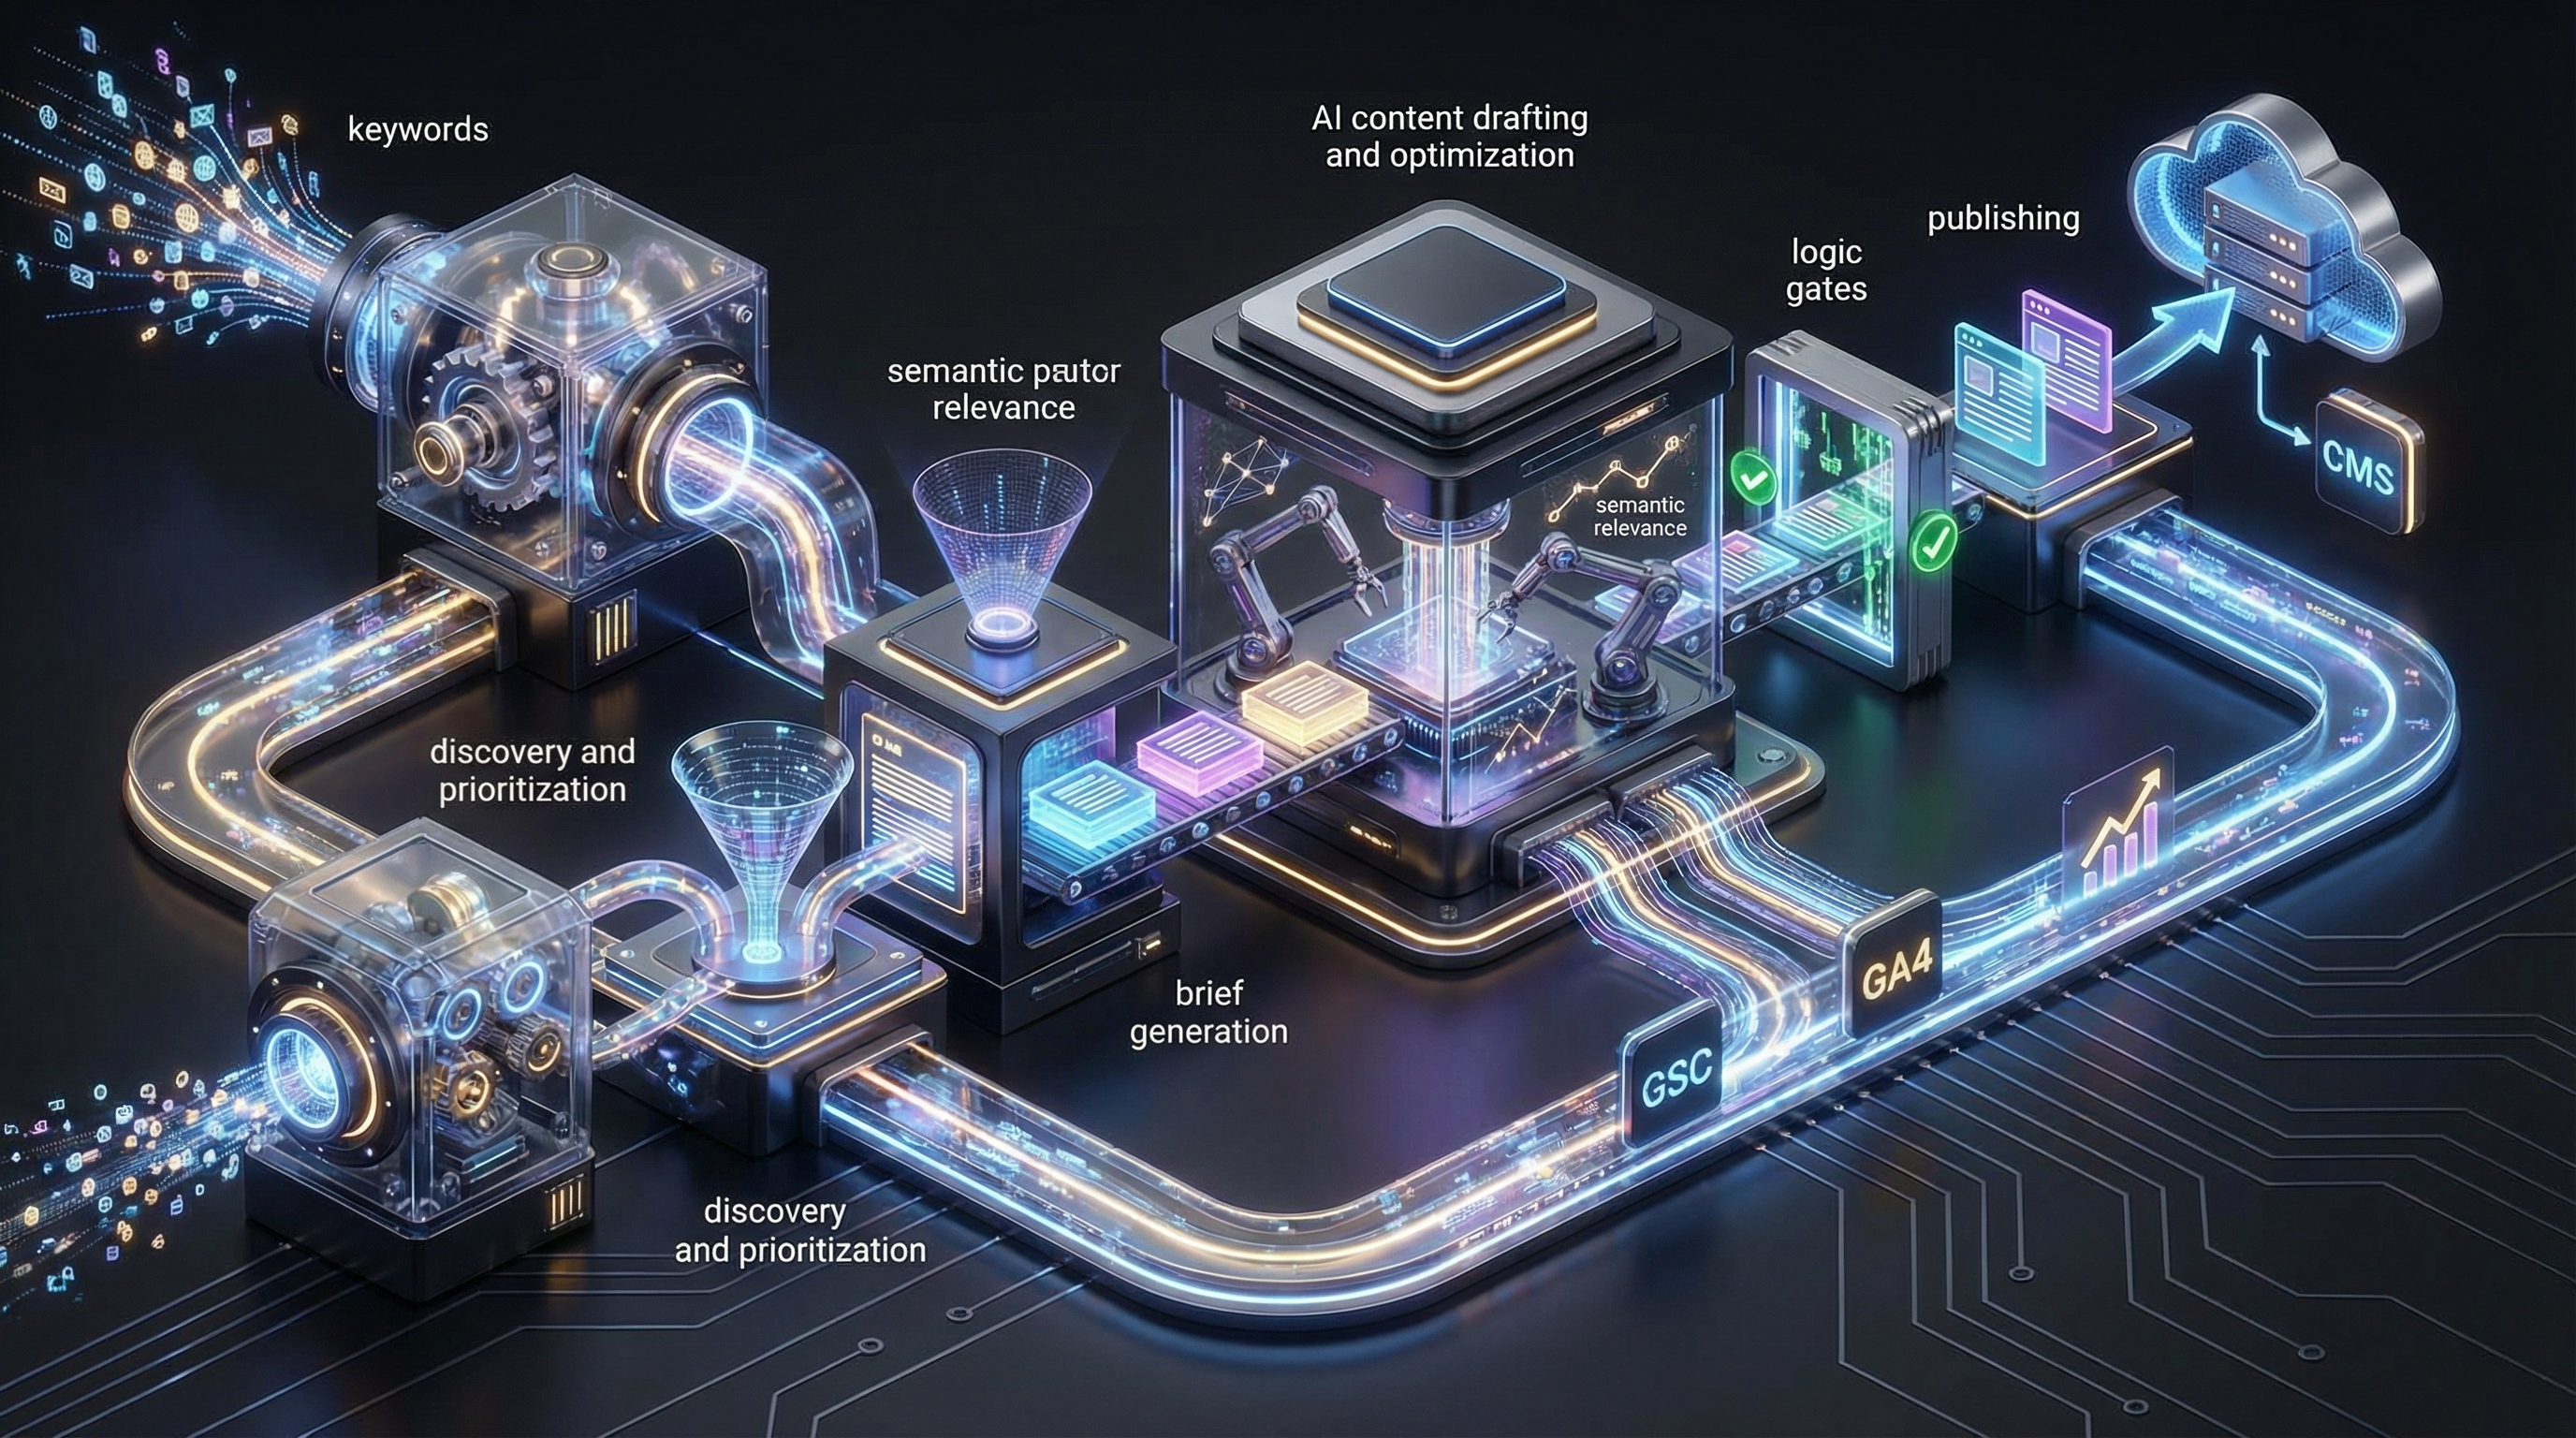
Keyword to Published Article Workflow Without Human Input: The Complete Autonomous SEO System
Most SEO teams are still running a manual assembly line — one person finds keywords, another briefs a writer, someone edits, someone publishes, and nobody has time to do it again next week. That's not a workflow. That's a bottleneck with a content calendar attached.
The idea of a keyword-to-published-article workflow without human input has moved from science fiction to operational reality. AI orchestration layers, autonomous publishing pipelines, and closed-loop SEO systems now exist that can take a raw keyword signal and output a live, indexed article — no writer, no editor, no project manager required [1]. In 2026, the question isn't whether this is possible. It's whether your stack is built to run it.
This guide breaks down exactly how a fully automated keyword-to-publish pipeline works — the architecture, the tools, the logic gates, and the failure points most teams miss — so you can stop babysitting your content and start running SEO like a system.
What a Keyword-to-Published Article Workflow Actually Means
Before building anything, you need to understand what the full pipeline scope actually covers. A keyword-to-published article workflow isn't just "AI writes a draft." It spans from the moment a keyword signal surfaces — whether from a search volume API, a competitor gap analysis, or a rank-decay alert — all the way through to a live URL sitting in Google's index. Every stage in between is part of the system.
Most teams think they've automated their content operations because they use an AI writing tool. They haven't. They've automated one stage out of six, and a human is still touching every other gate. That's not a pipeline. That's a human-assisted drafting tool dressed up as automation [2].
AI-Assisted vs. Fully Autonomous: A Critical Distinction
Here's the line that matters: AI-assisted means a human still approves, edits, or schedules at some stage. Fully autonomous means keyword in, published article out, no manual handoff.
Most tools on the market market automation but deliver assistance. They surface keyword ideas — you still approve them. They generate drafts — you still review them. They suggest publish times — you still click the button. Every one of those touchpoints is a bottleneck disguised as a feature.
The operator's real question isn't "does this tool use AI?" It's: where am I still the bottleneck? Map every stage where a human action is required before the next step can proceed. That's your automation gap. A genuinely autonomous pipeline eliminates every one of those gates, replacing human judgment with encoded logic rules.
The 6 Stages Every Autonomous Pipeline Must Cover
A complete autonomous SEO pipeline runs exactly six stages, and every single one must be automated for the system to be truly self-operating:
- Stage 1: Keyword discovery and prioritization — surface and queue keywords based on predefined rules
- Stage 2: Search intent classification — route each keyword to the correct content type before any content is generated
- Stage 3: Content brief generation — pull SERP structure, competitor patterns, and PAA data into a machine-ready brief
- Stage 4: Article drafting and SEO optimization — generate, structure, and optimize the article against targets
- Stage 5: Quality and compliance checks — automated gates that catch errors, thin content, and policy violations before publish
- Stage 6: CMS publishing and indexing trigger — push the final article to your CMS and fire the indexing signal
Miss any one of these stages and you haven't built a pipeline — you've built a partial workflow that still requires a human to cross the finish line.
Building the Keyword Discovery and Prioritization Layer
The pipeline starts with data quality. Garbage keywords in means garbage articles out, no matter how sophisticated your generation layer is. Autonomous keyword discovery pulls from multiple data sources simultaneously: search volume APIs, SERP scraping tools, competitor gap analysis feeds, and internal rank-tracking signals.
The prioritization logic is where most DIY systems fail. It's not enough to pull keyword data — the system needs rules that determine which keywords are worth queuing for content generation. Those rules typically include intent scoring, keyword difficulty thresholds, topical cluster mapping (so you're not writing three articles targeting the same concept), and commercial relevance filters.
A well-configured prioritization layer also handles keyword cannibalization automatically. In a high-volume automated pipeline, this becomes critical. Without deduplication logic comparing new keywords against your existing content index, you'll systematically generate competing articles for the same terms — diluting authority rather than building it [3].
Automated Intent Classification: Teaching the System What to Write
Intent classification must happen before content generation, not after. This is a sequencing mistake most teams make: they generate content and then realize it's the wrong format for the keyword's actual intent.
The system needs to classify every keyword as informational, commercial, or transactional before passing it downstream. Why? Because the content structure, word count target, CTA placement, and even the generation prompt are all different depending on intent. A transactional keyword needs a different article architecture than an informational one — and if you route them through the same template, you'll produce content that doesn't match what the SERP is rewarding.
Modern classification APIs and LLM-based intent scoring can handle this at scale without human review. Configure the routing logic once, test it against a sample of known-intent keywords, and let it run. The downstream pipeline is only as accurate as this classification gate.
Automated Content Brief Generation and Article Drafting
Once a keyword clears the intent gate, the system builds a structural brief automatically. This means pulling the top-ranking SERP results, extracting heading patterns, identifying PAA questions, mapping common subtopics, and compiling that data into a machine-readable brief that the generation model consumes directly — no human review, no content strategist in the middle [4].
The brief feeds directly into the drafting model. This is where prompt engineering at the system level becomes the equivalent of having a permanent editor on staff. Your generation prompts encode every rule your editor would enforce: heading hierarchy, word count targets, internal linking directives, brand voice rules, citation requirements, and SEO optimization parameters. The quality of your output at scale is a function of how well your system-level instructions are written.
How to Orchestrate AI Workflows Without Coding
You don't need an engineering team to build this pipeline. No-code and low-code orchestration layers — platforms like Make, n8n, or purpose-built SEO automation tools — connect every stage of the pipeline through a visual workflow interface [2].
Workflow triggers can be cron-based (run every Monday at 6am), event-based (trigger when a new keyword clears a difficulty threshold), or threshold-based (fire when a tracked URL drops below position 15). Each trigger type serves a different part of the pipeline.
The core automation chain looks like this: keyword data → intent classifier → brief generator → draft model → formatter → quality gate → CMS publisher. Each node passes its output to the next as structured data. The handoffs are API calls, not emails.
Where most DIY pipelines break is at the handoff points — mismatched data formats, API rate limits, or error handling gaps that cause silent failures. Build redundancy into every handoff: error logging, retry logic, and alerting rules so failures surface without requiring you to manually check pipeline health.
Maintaining Brand Voice and SEO Quality at Scale
Brand voice drift is real at volume. Article 1 sounds like your brand. Article 500 sounds like a different company wrote it. The fix is system-level style guides — voice rules, tone parameters, prohibited phrases, and structural templates encoded directly into your generation prompts, not maintained manually in a Google Doc that nobody updates.
Automated heading structure, meta description generation, and schema markup should all be part of the formatting stage. Internal link injection is a critical but often-skipped step: the system should map every new article to relevant existing cluster content and insert contextual links automatically — both in the new article and, where possible, in existing posts via CMS API.
Before anything hits publish, run automated quality scoring: readability score thresholds, keyword density checks, uniqueness validation, and minimum word count enforcement. These are pass/fail gates, not suggestions. If an article fails a gate, it routes to a remediation queue — not to a human.
Automated Quality Checks and Compliance Gates
A zero-human pipeline still needs review logic — it just can't be human review. Automated quality gates are the immune system of your content engine. Without them, errors, hallucinations, thin content, and policy violations go live at scale [5].
Automated fact-check flags work by cross-referencing specific claims — statistics, dates, named entities — against a trusted source list or knowledge base. They won't catch every error, but they'll surface high-confidence hallucination indicators: impossible dates, contradictory statistics, or references to entities that don't exist.
Duplicate content detection must run before every publish job. In bulk publishing environments, it's easy to generate near-duplicate content for semantically similar keywords without realizing it. Automated canonical logic and cosine similarity scoring against your existing content index catches this before it creates a thin-content problem.
For agencies running autonomous pipelines for clients in regulated industries — finance, health, legal — compliance gate logic becomes non-negotiable. Automated rules that flag specific claim types, require disclaimer insertion, or block publication pending a compliance tag are the only scalable solution.
What Makes AI Content Undetectable to Algorithms (and Why It Matters Less Than You Think)
The AI detection conversation is a distraction. The real risk isn't that Google identifies your content as AI-generated — it's that your content is thin, shallow, and low-E-E-A-T, regardless of who or what wrote it. Google's quality signals reward depth, specificity, structural coherence, and authority signals. None of those are about origin. They're about quality.
Building a system that produces substantive content beats trying to game detection tools every time. The structural quality signals that actually move rankings — content depth, topical specificity, internal linking density, authoritative source citations — are all engineerable at the system level.
Automated ways to add specificity include data injection (pulling real statistics from an approved data source library into generation prompts), example libraries (pre-built scenario banks that add concrete illustrations to abstract points), and source citation logic that references authoritative external sources at defined intervals. These aren't humanization tricks. They're quality engineering.
CMS Integration and Autonomous Publishing
The final production stage connects your formatted, quality-checked article to your CMS via API. Whether you're running WordPress, Webflow, Contentful, or a headless CMS, most platforms expose publishing endpoints that accept structured content payloads [3].
Automated metadata population means the system generates and assigns title tags, slugs, canonical URLs, OG tags, and featured image alt text without human input. Scheduling logic defines publish timing based on crawl frequency patterns and historical index behavior — spreading publishes to avoid triggering spam signals from sudden volume spikes.
When a new article publishes, the pipeline should also fire automated internal link updates in existing posts — finding relevant anchor text in published content and inserting links to the new URL. This is one of the most powerful and most-skipped automation steps in most content pipelines.
The final pipeline step is a sitemap ping and Google Indexing API call, triggering Google's crawler to process the new URL rather than waiting for passive discovery. Median time to indexing drops significantly with active indexing triggers compared to passive crawl discovery.
Which Services and Apps Enable Autonomous Publishing Workflows
The tool landscape splits into two categories: general-purpose orchestration platforms and purpose-built SEO automation systems.
General-purpose tools — Zapier, Make, n8n — connect generation outputs to CMS publishing endpoints through a series of configured steps. They're flexible but create fragility at scale. Stitching together 10 tools means 10 failure points, 10 API rate limits to manage, and 10 vendor changes that can break your pipeline without warning.
Purpose-built SEO automation platforms, by contrast, run the entire pipeline in a single system. No stitching, no middleware management, no cross-tool debugging. The keyword discovery layer, brief generator, drafting model, quality gates, and CMS publisher are all integrated — meaning each stage has visibility into every other stage, and failure handling is centralized. If you're serious about running this at scale, the unified system approach is the only one that doesn't fall apart at volume.
Continuous Optimization: Closing the Loop After Publish
A true autonomous system doesn't stop at publish. Stopping at publish means you've built a content factory, not a content engine. The difference is feedback.
The post-publish loop feeds rank tracking data back into the pipeline to trigger content refreshes automatically. When a tracked URL drops below a rank threshold, loses CTR, or hits an impressions plateau, the system identifies it as a re-optimization candidate — without a human having to audit the site or run a content decay report [5].
Automated re-optimization jobs pull the current ranking signals for the target keyword, analyze what's changed in the SERP since the original publish date, generate an updated version, run it through the quality gates, and republish — without any manual review. The content self-corrects based on real-world performance data.
The compounding effect here is significant. Every optimization cycle generates data about what works. That data improves the next generation cycle. Over time, a self-optimizing system doesn't just maintain quality — it improves it, systematically, without requiring any incremental human effort.
Turning SEO Into a System That Runs Itself
The closed-loop architecture looks like this: discovery → generation → publish → monitor → optimize → repeat. Each cycle produces data that feeds the next. Keyword prioritization gets smarter as performance data accumulates. Generation quality improves as style rules get refined based on what ranks. Publishing timing gets more precise as crawl pattern data builds.
Operators who set this up correctly stop trading time for content output. The system doesn't need more headcount to scale — it needs better rules. That's the fundamental difference between a content calendar (a list of tasks that require human execution) and a content engine (a system that executes itself).
Common Failure Points in Autonomous SEO Pipelines (and How to Engineer Around Them)
Building the pipeline is step one. Keeping it running is the real engineering challenge. Here are the six failure points that take down most autonomous content systems:
Failure Point 1: Keyword input quality. The pipeline can only work with the signal you feed it. Uncurated keyword lists with irrelevant terms, duplicate concepts, or wrong-market intent will flood your queue with worthless content jobs. Configure your input filters tightly.
Failure Point 2: Intent misclassification. A single misconfigured intent routing rule produces the wrong content type for dozens of keywords before anyone catches it. Test your classifier against a validation set of labeled keywords before deploying at full volume.
Failure Point 3: No quality gate before publish. The most catastrophic failure mode. Content with factual errors, duplicate sections, or below-threshold quality goes live at scale. Every pipeline needs a mandatory pass/fail quality check between generation and publish, with failed articles routing to a remediation queue — not a human inbox.
Failure Point 4: CMS API rate limits. Batch publishing jobs hit API rate limits and fail silently. Build retry logic, rate-limit-aware batching, and publish queue management into your CMS integration layer.
Failure Point 5: No feedback loop. A pipeline that publishes but never monitors is a content factory with no quality control. The system needs to track performance and use that data to optimize — or you're just running a very fast manual process.
Failure Point 6: Brand voice drift at scale. Generation prompts that work for article 1 often degrade subtly by article 100. Build automated voice consistency checks — comparing new output against benchmark articles — and schedule periodic prompt audits into your system maintenance workflow.
For all six failure points, the fix is the same: monitoring, alerting, and automated remediation logic. Failures in autonomous systems should surface as alerts, not as support tickets from your clients or Google penalties in your Search Console.
The Bottom Line
A keyword-to-published article workflow without human input isn't a hack or a shortcut — it's a systems engineering problem. The operators winning at SEO in 2026 aren't hiring more writers or buying more tools. They've built a pipeline where keyword discovery feeds brief generation, brief generation feeds drafting, drafting feeds automated QA, and QA feeds publish — on a loop, without a human in the chain.
Every stage is a logic gate. Every output becomes an input. That's not content marketing. That's an SEO engine.
The teams still running manual assembly lines — approving keyword lists, reviewing drafts, clicking publish, and wondering why they can't scale — are competing against systems that don't sleep, don't get backlogged, and get measurably better with every cycle.
If you're ready to stop being the bottleneck in your own content operation, see how Ranklynk runs the entire pipeline — keyword to published article — without human input.
Frequently Asked Questions
Q: How to make an article not AI-generated?
Making an article appear less AI-generated involves several editorial and structural techniques. First, inject personal anecdotes, brand-specific data, or proprietary insights that AI cannot fabricate — real case studies, internal metrics, and first-person expertise signal human authorship. Second, vary your sentence rhythm deliberately; AI tends toward uniform sentence length and predictable transitions. Third, use unconventional formatting choices: break grammar rules intentionally, use colloquialisms, and structure arguments in non-linear ways. Fourth, incorporate real-time references — current events, recent statistics from 2026, or trending industry examples — that AI models may not have in their training data. Fifth, add expert quotes sourced through direct outreach rather than paraphrasing existing published material. In the context of a keyword-to-published-article workflow without human input, quality control logic gates can be built to automatically enrich AI-generated drafts with proprietary data feeds, brand voice rules, and freshness signals before publishing — reducing detection risk at scale without requiring manual editing.
Q: Which tool allows you to include AI-powered features in workflows without writing extensive code?
Several no-code and low-code platforms allow teams to embed AI-powered features into automated workflows without extensive programming. Make (formerly Integromat) is a leading option, offering native AI modules that connect to OpenAI, Anthropic, and other LLM APIs through a visual drag-and-drop interface. Zapier similarly provides AI steps that can be dropped into multi-app automation sequences. n8n is a popular open-source alternative that supports complex AI orchestration with minimal coding requirements. For content-specific pipelines, tools like Bardeen, Relevance AI, and Gumloop offer purpose-built AI workflow builders. These platforms are central to building a keyword-to-published-article workflow without human input because they serve as the orchestration layer — connecting keyword research APIs, AI writing tools, CMS platforms, and publishing endpoints into a single automated sequence that requires no developer intervention to operate.
Q: Which service enables you to build the workflows that are required?
The most capable services for building end-to-end autonomous content workflows in 2026 are Make (Integromat), n8n, and Zapier at the orchestration level, combined with specialized AI content platforms like Jasper, Surfer SEO, and Frase for generation and optimization. For teams building a keyword-to-published-article workflow without human input, the stack typically requires at least three layers: a workflow orchestration service (Make or n8n), an AI content generation API (OpenAI, Anthropic, or a fine-tuned model), and a CMS integration service (WordPress REST API, Webflow API, or similar). Cloud services like AWS, Google Cloud, and Azure also enable custom pipeline builds for enterprise teams needing more control. The right service depends on your technical resources, publishing volume, and how much customization your quality control logic requires. For most SEO teams, Make combined with OpenAI and a WordPress REST API integration covers the full pipeline scope without requiring a dedicated engineering team.
Q: Which app allows you to create workflows between your apps, files, and data to automate time-consuming tasks?
Zapier is the most widely recognized app for creating automated workflows between applications, files, and data sources without coding. It connects over 6,000 apps and allows users to build 'Zaps' — automated sequences triggered by specific events across platforms. Make (formerly Integromat) is a more powerful alternative for complex, multi-step workflows that involve conditional logic, data transformation, and iterative loops. n8n is the preferred choice for teams that want open-source flexibility and deeper API control. Microsoft Power Automate serves enterprise environments already operating within the Microsoft ecosystem. In the context of a keyword-to-published-article workflow without human input, these apps serve as the connective tissue — automating the handoff between keyword discovery tools, AI writing platforms, SEO optimization tools, image generation APIs, and CMS publishing endpoints. Without a workflow automation app at the center of the stack, each stage remains a manual handoff, which defeats the purpose of autonomous content operations.
Q: How to avoid AI detection in article writing?
Avoiding AI detection in article writing requires both structural and substantive strategies. At the structural level, use varied sentence lengths, unconventional paragraph breaks, and non-formulaic transitions that deviate from typical AI output patterns. At the substantive level, ground the content in proprietary data, specific examples, and expert perspectives that AI detectors cannot attribute to a generic language model. Tools like Undetectable AI, Humanizer Pro, and QuillBot can reprocess AI-generated text to reduce detector scores, though results vary by platform. More reliably, building brand voice guidelines into your AI prompts from the start — including tone, vocabulary preferences, and structural rules — produces output that is inherently less detectable. For teams running a keyword-to-published-article workflow without human input, integrating a post-generation humanization step into the pipeline before publishing is an effective automated safeguard. It is worth noting that Google's current stance focuses on content quality and helpfulness rather than penalizing AI origin, so detection avoidance should prioritize genuine value over technical obfuscation.
Q: How do I remove AI from an article?
Removing obvious AI characteristics from an article involves targeted rewriting of the sections most likely to trigger detection or feel generic. Start by identifying overused AI phrases — terms like 'delve into,' 'it's worth noting,' 'in conclusion,' and 'as an AI language model' — and replace them with direct, specific language. Restructure any passages that follow a predictable thesis-evidence-summary loop, which is a common AI writing pattern. Add concrete details: real numbers, named sources, specific dates, and attributed quotes that ground the content in verifiable reality. Replace generic transitions with opinionated, voice-driven connective statements. For teams operating a keyword-to-published-article workflow without human input at scale, building an automated post-processing prompt into the pipeline — one that specifically targets and rewrites high-risk phrases before publishing — achieves consistent AI-removal without manual editing. Run the final output through detection tools like Originality.ai or GPTZero as a quality gate before the article goes live.
Q: How to orchestrate AI workflows without coding?
Orchestrating AI workflows without coding is now fully achievable using visual automation platforms. Make (Integromat) and Zapier are the most accessible starting points, both offering pre-built AI modules that connect to OpenAI, Google Gemini, and Anthropic APIs through point-and-click interfaces. n8n provides a visual node-based workflow builder that requires minimal code even for complex logic branches. Relevance AI and Gumloop are purpose-built for AI agent orchestration without engineering resources. The key to no-code AI orchestration is defining your workflow logic before touching any tool — map every stage, every trigger condition, every output format, and every failure fallback in a flowchart first. For a keyword-to-published-article workflow without human input, this means documenting the exact sequence from keyword ingestion to CMS publishing, then rebuilding that sequence inside your chosen platform using native AI modules. Most complete autonomous content pipelines can be built in Make or n8n within a few days without writing a single line of custom code.
Q: What are the 4 types of AI?
The four foundational types of AI, based on capability classification, are: Reactive Machines, Limited Memory, Theory of Mind, and Self-Aware AI. Reactive Machines respond to immediate inputs without memory or context — early chess programs like Deep Blue are the classic example. Limited Memory AI learns from historical data to inform current decisions — this is the category that encompasses today's large language models, including GPT-4o and Claude, which power most content generation tools. Theory of Mind AI would understand emotions, intentions, and social context, but this type does not yet exist at a practical operational level as of 2026. Self-Aware AI — machines with genuine consciousness and self-understanding — remains theoretical. For practical purposes in building a keyword-to-published-article workflow without human input, Limited Memory AI is the operative category. These models process training data, follow prompt instructions, and generate contextually relevant content, making them the engine of every autonomous SEO pipeline currently in production.
References
[1] https://rankyak.com/blog/automated-content-generation. rankyak.com. https://rankyak.com/blog/automated-content-generation
[2] https://www.trysight.ai/blog/automate-content-creation-workflow. trysight.ai. https://www.trysight.ai/blog/automate-content-creation-workflow
[3] https://www.activepieces.com/blog/content-publishing-workflow. activepieces.com. https://www.activepieces.com/blog/content-publishing-workflow
[4] https://community.hubspot.com/t5/Blog-Website-Page-Publishing/How-to-Build-a-Better-AI-Content-Generation-Workflow/m-p/1036220. community.hubspot.com. https://community.hubspot.com/t5/Blog-Website-Page-Publishing/How-to-Build-a-Better-AI-Content-Generation-Workflow/m-p/1036220
[5] https://www.frase.io/blog/ai-agents-for-seo. frase.io. https://www.frase.io/blog/ai-agents-for-seo