Keyword Research Automation for Content Gaps: Build the System That Finds Them Before Your Competitors Do
Most SEO teams are still manually crawling competitor URLs, exporting spreadsheets, and color-coding keyword gaps like it's 2018. Meanwhile, the sites eating their lunch have automated the entire discovery-to-publish pipeline.
Content gap analysis used to mean hours of cross-referencing competitor keyword rankings, filtering by intent, and guessing which topics were worth pursuing. Today, keyword research automation tools and AI-driven workflows can surface those gaps continuously — without a human in the loop. The market for SEO automation has matured fast [1], and operators who haven't systematized their gap analysis are leaving compounding organic traffic on the table.
This guide breaks down exactly how keyword research automation for content gaps works, which workflows and tools actually move the needle, and how to build a closed-loop system that discovers, prioritizes, and acts on gaps — without manual effort eating your team's bandwidth.
What Is Keyword Research Automation for Content Gaps — and Why Manual Analysis Is a Bottleneck
Content gap analysis is the delta between what your competitors rank for and what your site doesn't [2]. Simple concept. Brutal execution at scale. You pull competitor ranking data, cross-reference it against your own keyword universe, filter by intent and volume, and identify the topics you're missing. Then you do it again next month. And the month after that.
The problem isn't the analysis itself — it's the recurring nature of it. Gaps don't stay static. A competitor publishes a new cluster of content, earns rankings, and suddenly there are 40 new gaps in your topical map. If your process for detecting that is a quarterly audit, you're already three months behind.
Manual gap analysis doesn't scale — especially across multiple clients or high-volume content operations. For agencies managing 10+ domains, it's not just slow. It's structurally broken.
The Hidden Cost of Manual Keyword Gap Workflows
A thorough manual gap audit takes 4–8 hours per domain [3]. That's not including the time to prioritize, brief, and assign content. For an agency with 20 clients, running monthly gap audits means 80–160 hours per month on a single workflow. That's a full-time hire just to maintain the process — before a single word of content gets written.
The opportunity cost compounds it. Gaps identified in real-time can be acted on before competitors double down. Gaps identified monthly are already being won by someone else. Every week of lag in your discovery cycle is a week of organic traffic you'll never recover.
The scalability ceiling hits hard around 10 clients. Below that, manual workflows feel manageable. Above it, they collapse — replaced by prioritization decisions driven by whoever has the loudest client, not the best opportunity data.
What 'Automated' Actually Means in This Context
Automation in this context doesn't mean a faster spreadsheet. It means continuous crawling, competitor monitoring, and keyword clustering that runs without human triggers. The system watches your competitor set, detects new rankings, identifies gaps against your domain, scores them by opportunity, and routes them into your content pipeline — on its own schedule, not yours.
There's an important distinction between semi-automated and fully automated workflows. Semi-automated means you're still pulling reports, interpreting outputs, and manually routing tasks. Fully automated means the system triggers content creation when a gap meets a threshold — no analyst in the loop.
For operators at scale, that distinction is the difference between a tool that helps you work faster and a system that works while you sleep.
How Keyword Research Automation Works: The Core Mechanics
The technical pipeline for automated gap analysis has four stages: data ingestion, gap detection, prioritization, and output. Each stage can be automated. Most operators only automate the first one and wonder why their workflow still feels manual.
Step 1 — Automated Competitor Keyword Ingestion
The system starts by continuously pulling live ranking data from a defined competitor set. Modern SEO platforms can monitor hundreds of domains and track keyword movements daily — or more frequently for high-velocity SERPs. This isn't a monthly export. It's a live feed.
Frequency matters. Daily ingestion lets you detect when a competitor publishes a new article and starts ranking. Weekly ingestion means you're reacting to trends, not leading them. Real-time ingestion is the theoretical ceiling — practically, daily is the operational sweet spot for most content programs.
Multi-competitor monitoring is where the leverage compounds. You're not watching one competitor; you're watching the entire domain set that overlaps with your topical territory. Every new ranking any of them earns is a potential gap signal.
Step 2 — Gap Detection and Intent Filtering
Raw gap data is noisy. Not every keyword your competitor ranks for represents an opportunity for your site. Automated systems apply intent classification layers to filter the signal from the noise [4].
A true gap has three properties: your competitor ranks for it, you don't, and it aligns with your topical authority and commercial goals. An automated intent filter separates informational gaps (blog content, educational hubs) from commercial and transactional gaps (comparison pages, feature pages, pricing-adjacent content). Each type routes to a different part of your content pipeline.
Filtering by difficulty, volume floor, and topical alignment reduces the gap list from hundreds of raw signals to a prioritized queue of actionable opportunities. This is where AI-driven NLP layers earn their value — clustering semantically related terms, identifying topic families, and removing near-duplicate signals that would otherwise inflate the gap count.
Step 3 — Prioritization and Output Formatting
Not all gaps are equal. A scoring model ranks opportunities by combining search volume, keyword difficulty, topical authority fit, and strategic value. The output isn't a flat list — it's a ranked queue, with the highest-leverage gaps surfaced first.
Automated clustering groups related gaps into content briefs or topic pillars. Instead of 40 individual keyword targets, you get five clustered topics, each supporting a core content piece with defined supporting subtopics. This is the architecture of topical authority, built automatically.
Output formats vary by system. The minimum viable output is a keyword list. The maximum viable output is a fully formatted content brief, routed directly into your CMS or editorial queue, with a publishing trigger set. The gap between those two output states is where most operators stall.
The Right Tool Stack for Automated Content Gap Analysis
The tool landscape splits into two categories: standalone gap analysis tools and full-stack automation platforms. Understanding the difference is critical before you invest in either.
Standalone Gap Analysis Tools vs. Full-Stack Automation Platforms
Standalone tools like Ahrefs Content Gap and Semrush Keyword Gap are powerful data surfaces [2]. They pull competitor rankings, identify gaps, and let you filter by volume, difficulty, and intent. They're excellent at discovery. But they stop there. Execution — briefing, assigning, publishing — still requires a human handoff.
Full-stack platforms handle the discovery-through-publishing loop in a single system. Gap detection triggers brief generation. Brief generation triggers content creation. Content creation triggers publishing. The operator's job is configuration and oversight, not execution.
For operators running one or two sites with high editorial control, standalone tools plus a manual workflow may be sufficient. For agencies managing 10+ clients or SaaS founders who need organic traffic without a content team, the manual handoff is the bottleneck. Full-stack automation eliminates it.
What to Look for in an Automated Keyword Research System
Four capabilities separate systems worth building on from tools that just add complexity:
Continuous monitoring vs. on-demand reports. The system should run on a schedule, not wait for you to log in and click a button.
CMS and publishing workflow integration. Gap outputs should flow directly into your content pipeline without a copy-paste step.
Customizable gap scoring. Different clients, different niches, and different content strategies require different scoring weights. The system should support custom logic, not just default templates.
Performance feedback loops. Once content publishes and earns rankings, the system should recognize the gap is closed, remove it from the queue, and surface the next opportunity. Without this, you're building a one-directional pipeline, not a self-improving system.
Building an Automated Content Gap Workflow: A Step-by-Step System
This is the part that actually moves the needle. Build this once, configure it correctly, and it runs without recurring human input. That's the standard to hold it to.
Step 1 — Define Your Competitor Set and Topical Perimeter
Start with three tiers of competitors: direct (same product, same audience), indirect (different product, overlapping keyword territory), and aspirational (sites you want to displace over a 12-month horizon). Each tier contributes different types of gap signals.
Set topical boundaries. If you're a B2B SaaS in project management, you don't need gap signals from a competitor's content about general productivity tips unless it converts. Define your topical perimeter by keyword clusters that map to your ICP and your commercial goals. Everything outside the perimeter is noise.
Revisit competitor sets quarterly. Markets shift. New competitors emerge. Existing ones pivot their content strategy. The competitor set that was accurate in Q1 may be stale by Q3 [5].
Step 2 — Configure Your Gap Detection Rules
Set a volume floor that filters out searches too low-frequency to justify content investment. Set a difficulty ceiling that matches your domain authority — there's no point surfacing opportunities you can't compete for yet. Apply intent filters to ensure the gaps you're acting on align with where your audience is in the funnel.
Exclude branded terms, navigational queries, and the competitor's product-specific pages. These are gaps in data only — they're not actionable for your site.
Build custom scoring logic for your specific niche. A fintech company weights YMYL content differently than a media publisher. An e-commerce operator cares about transactional intent above all else. The default scoring model in most tools is a starting point, not a final answer.
Step 3 — Route Gaps Into a Publishing Pipeline
This is the step most operators skip — and it's why their gap analysis produces reports instead of rankings.
Connect your gap detection output to a content brief generation layer. When a gap clears your scoring threshold, the system should automatically generate a brief: target keyword, supporting terms, intent classification, recommended content type, suggested word count, and internal linking opportunities.
From there, the brief routes into your content creation workflow — whether that's an AI writing system, a freelance network, or an internal editorial queue. Set a publishing trigger: when a gap scores above a defined threshold and no existing content covers it, content creation initiates automatically. No analyst required to make that call.
Step 4 — Close the Loop With Rank Tracking and Gap Re-Evaluation
A gap discovery system without a feedback loop is just a fancier way to generate a backlog. The loop closes when published content earns rankings, the system detects those rankings, marks the gap as closed, and surfaces the next-highest opportunity.
Automate the re-scoring process. As your site gains topical authority in a cluster, the difficulty weighting for adjacent keywords should decrease — you've earned the right to compete for more competitive terms. Build that logic into your scoring model.
The system that exists 12 months from now should be smarter than the one you configure today. Every content cycle — publish, rank, close gap, surface new gap — should make the prioritization model more accurate. That's a self-improving system.
Common Mistakes That Kill Automated Content Gap Systems
Most operators make the same five mistakes when building gap analysis automation:
Treating it as a one-time project. Gap analysis is a continuous process, not a quarterly audit. A system you run once produces a static list. A system that runs continuously produces a compounding content advantage.
Over-indexing on volume. High-volume gaps are the most competitive. Often, the highest-ROI opportunities are mid-volume, low-difficulty gaps in topic clusters where you already have authority. Volume is one input, not the output.
Stopping at discovery. The system that surfaces gaps but requires a human to act on them isn't an automation — it's a reporting tool. Execution is where the leverage lives.
Ignoring topical clustering. Targeting isolated gaps instead of building content depth around topic pillars fragments your authority signal. The system should cluster gaps into pillar-and-spoke structures, not route them as individual assignments.
No performance feedback. If your prioritization model doesn't update based on what's actually working, you're running a static algorithm in a dynamic environment. Performance data must feed back into scoring.
Each of these mistakes compounds the others, creating systems that look functional on dashboards but fail to produce meaningful ranking gains in practice. Understanding why they happen helps you design safeguards before they become embedded in your workflow.
The one-time project mentality often stems from treating keyword research automation as a technical build rather than an operational function. Teams invest heavily in the initial setup, celebrate the first batch of gap reports, then quietly deprioritize maintenance as other projects compete for attention. The fix is straightforward: schedule automated gap scans to run on a recurring cadence — weekly for competitive verticals, biweekly for slower-moving niches — and wire outputs directly into your content calendar system so discovery triggers action without human intervention.
The volume obsession is arguably the most costly mistake in practice. When your automation ranks every opportunity by search volume alone, it sends your writers toward the most congested keyword territory, where you're competing against established domain authorities with years of backlink momentum. A more effective scoring model weights topical authority match — how closely a gap aligns with clusters where your domain already ranks — alongside difficulty and volume. A 400-search-per-month keyword in a cluster where you hold three top-five positions is often worth more than a 4,000-volume gap in territory you've never touched.
Ignoring topical clustering deserves special attention because it's the mistake that actively works against your existing momentum. Search engines reward content ecosystems, not isolated pages. When your system routes individual gap opportunities as standalone assignments without mapping them to a parent pillar, you're producing orphaned content that struggles to inherit or pass authority. Build cluster mapping directly into your gap qualification logic: every identified gap should be automatically tagged to its nearest pillar topic before it enters the content queue.
Finally, the absence of performance feedback loops is what separates systems that plateau from systems that improve. After publishing gap-driven content, track ranking trajectory at 30, 60, and 90-day intervals and pipe that data back into your scoring model. If mid-difficulty gaps in cluster-dense topics consistently outperform high-volume standalone targets, your algorithm should learn that pattern and weight future opportunities accordingly. This closed-loop design transforms your keyword research automation from a static prioritization tool into a self-improving content intelligence system.
Keyword Research Automation for Agencies: Scaling Gap Analysis Across Client Portfolios
Agencies face a specific version of this problem: they need to run gap analysis across 10–50 client domains simultaneously, on a recurring cadence, with client-facing deliverables. Manual workflows don't survive contact with that requirement.
Multi-Client Configuration and Isolation
Each client needs a separate competitor set, scoring configuration, and topical perimeter. A healthcare client and a SaaS client don't share keyword territory, intent priorities, or difficulty thresholds. The system must support per-client configuration without cross-contamination of data or outputs.
Reporting automation is a force multiplier. Auto-generated gap reports per client, on a defined cadence, eliminate the analyst hours currently spent assembling monthly deliverables. The system produces the report; the strategist adds context and recommendations. That's a 10x improvement in output-per-hour.
Turning Gap Analysis Into a Scalable Agency Service
Automated gap analysis reframes what an agency sells. Instead of selling execution — hours of manual research — you're selling a continuously running system that surfaces opportunities your competitors' agencies miss. That's a different value proposition, and a more defensible one.
When you can show a client a live dashboard of content gaps ranked by opportunity, updated daily, connected to a publishing queue that's already moving — you've shifted the conversation from "here's what we found" to "here's what the system found and here's what's already in progress." Clients don't pay for that with monthly retainers sized for manual labor. They pay for it with long-term contracts sized for compounding results.
To make multi-client automation work in practice, agencies need to invest in a configuration layer that sits above the automation tools themselves. This typically means building client-specific YAML or JSON profiles that define competitor domains, primary keyword clusters, branded exclusion lists, and intent weighting rules. Without this abstraction layer, every configuration change becomes a manual intervention — and you've recreated the bottleneck you were trying to eliminate.
Prioritization logic also needs to be client-aware. A B2B SaaS client with a 90-day sales cycle weights informational top-of-funnel gaps differently than an eCommerce client optimizing for transactional volume. Your automation system should support configurable scoring matrices that weight keyword difficulty, search volume, conversion intent, and topical authority independently per client — not apply a one-size-fits-all scoring model across the entire portfolio.
For agencies managing 20 or more clients, a tiered alert system becomes essential. Not every gap finding warrants a strategist's attention. Configure thresholds so the system escalates only high-opportunity gaps — those exceeding a volume floor, falling within an achievable difficulty range, and matching an active content category — while lower-priority findings queue for monthly review. This separates signal from noise at scale and protects analyst time for work that actually requires human judgment.
On the commercial side, the shift from manual deliverables to automated reporting also changes how you structure pricing. Agencies that have successfully productized gap analysis typically offer it as a tiered add-on: a base tier that delivers monthly automated reports, a mid tier that includes weekly updates and priority alerts, and a premium tier that connects gap findings directly to a managed content production workflow. Each tier has a defined SLA and a corresponding price point — moving the conversation away from hourly rates entirely.
Finally, consider how automated gap analysis strengthens client retention. When clients receive a recurring report showing identified opportunities, content produced against those opportunities, and ranking progress over time, the ROI narrative writes itself. Churn risk drops when clients can see the flywheel turning. Agencies using this model in 2026 report contract renewal rates significantly above industry averages — not because the relationship is stickier emotionally, but because the system's output is visibly and measurably compounding month over month. Learn more about Best Automated Content Gap Analysis Tools 2026.
From Gap Discovery to Published Content: The Fully Autonomous Pipeline
Gap discovery without execution is a fancier spreadsheet. The operators compounding their organic traffic right now aren't running better research processes — they've eliminated the handoff between research and publishing entirely. Learn more about Identify Content Gaps Automatically for Client Sites.
Why Discovery Without Execution Is Just a Fancier Spreadsheet
Every tool that surfaces gaps but stops at the report is asking you to do the hard part manually. And the hard part — briefing, assigning, writing, editing, publishing — is where the time actually goes. If your automation handles 20% of the workflow and leaves 80% to humans, you haven't built a system. You've built a faster first step. Learn more about 9 Best Automated Content Gap Analysis Tools.
The compounding advantage belongs to operators who've closed that gap. When a gap is detected on Monday and a published article is live by Friday — without a human making that call — the velocity advantage over manual operators is structural, not marginal. Learn more about Content Gap Analysis Without Manual Audits.
What a Closed-Loop Autonomous SEO System Looks Like
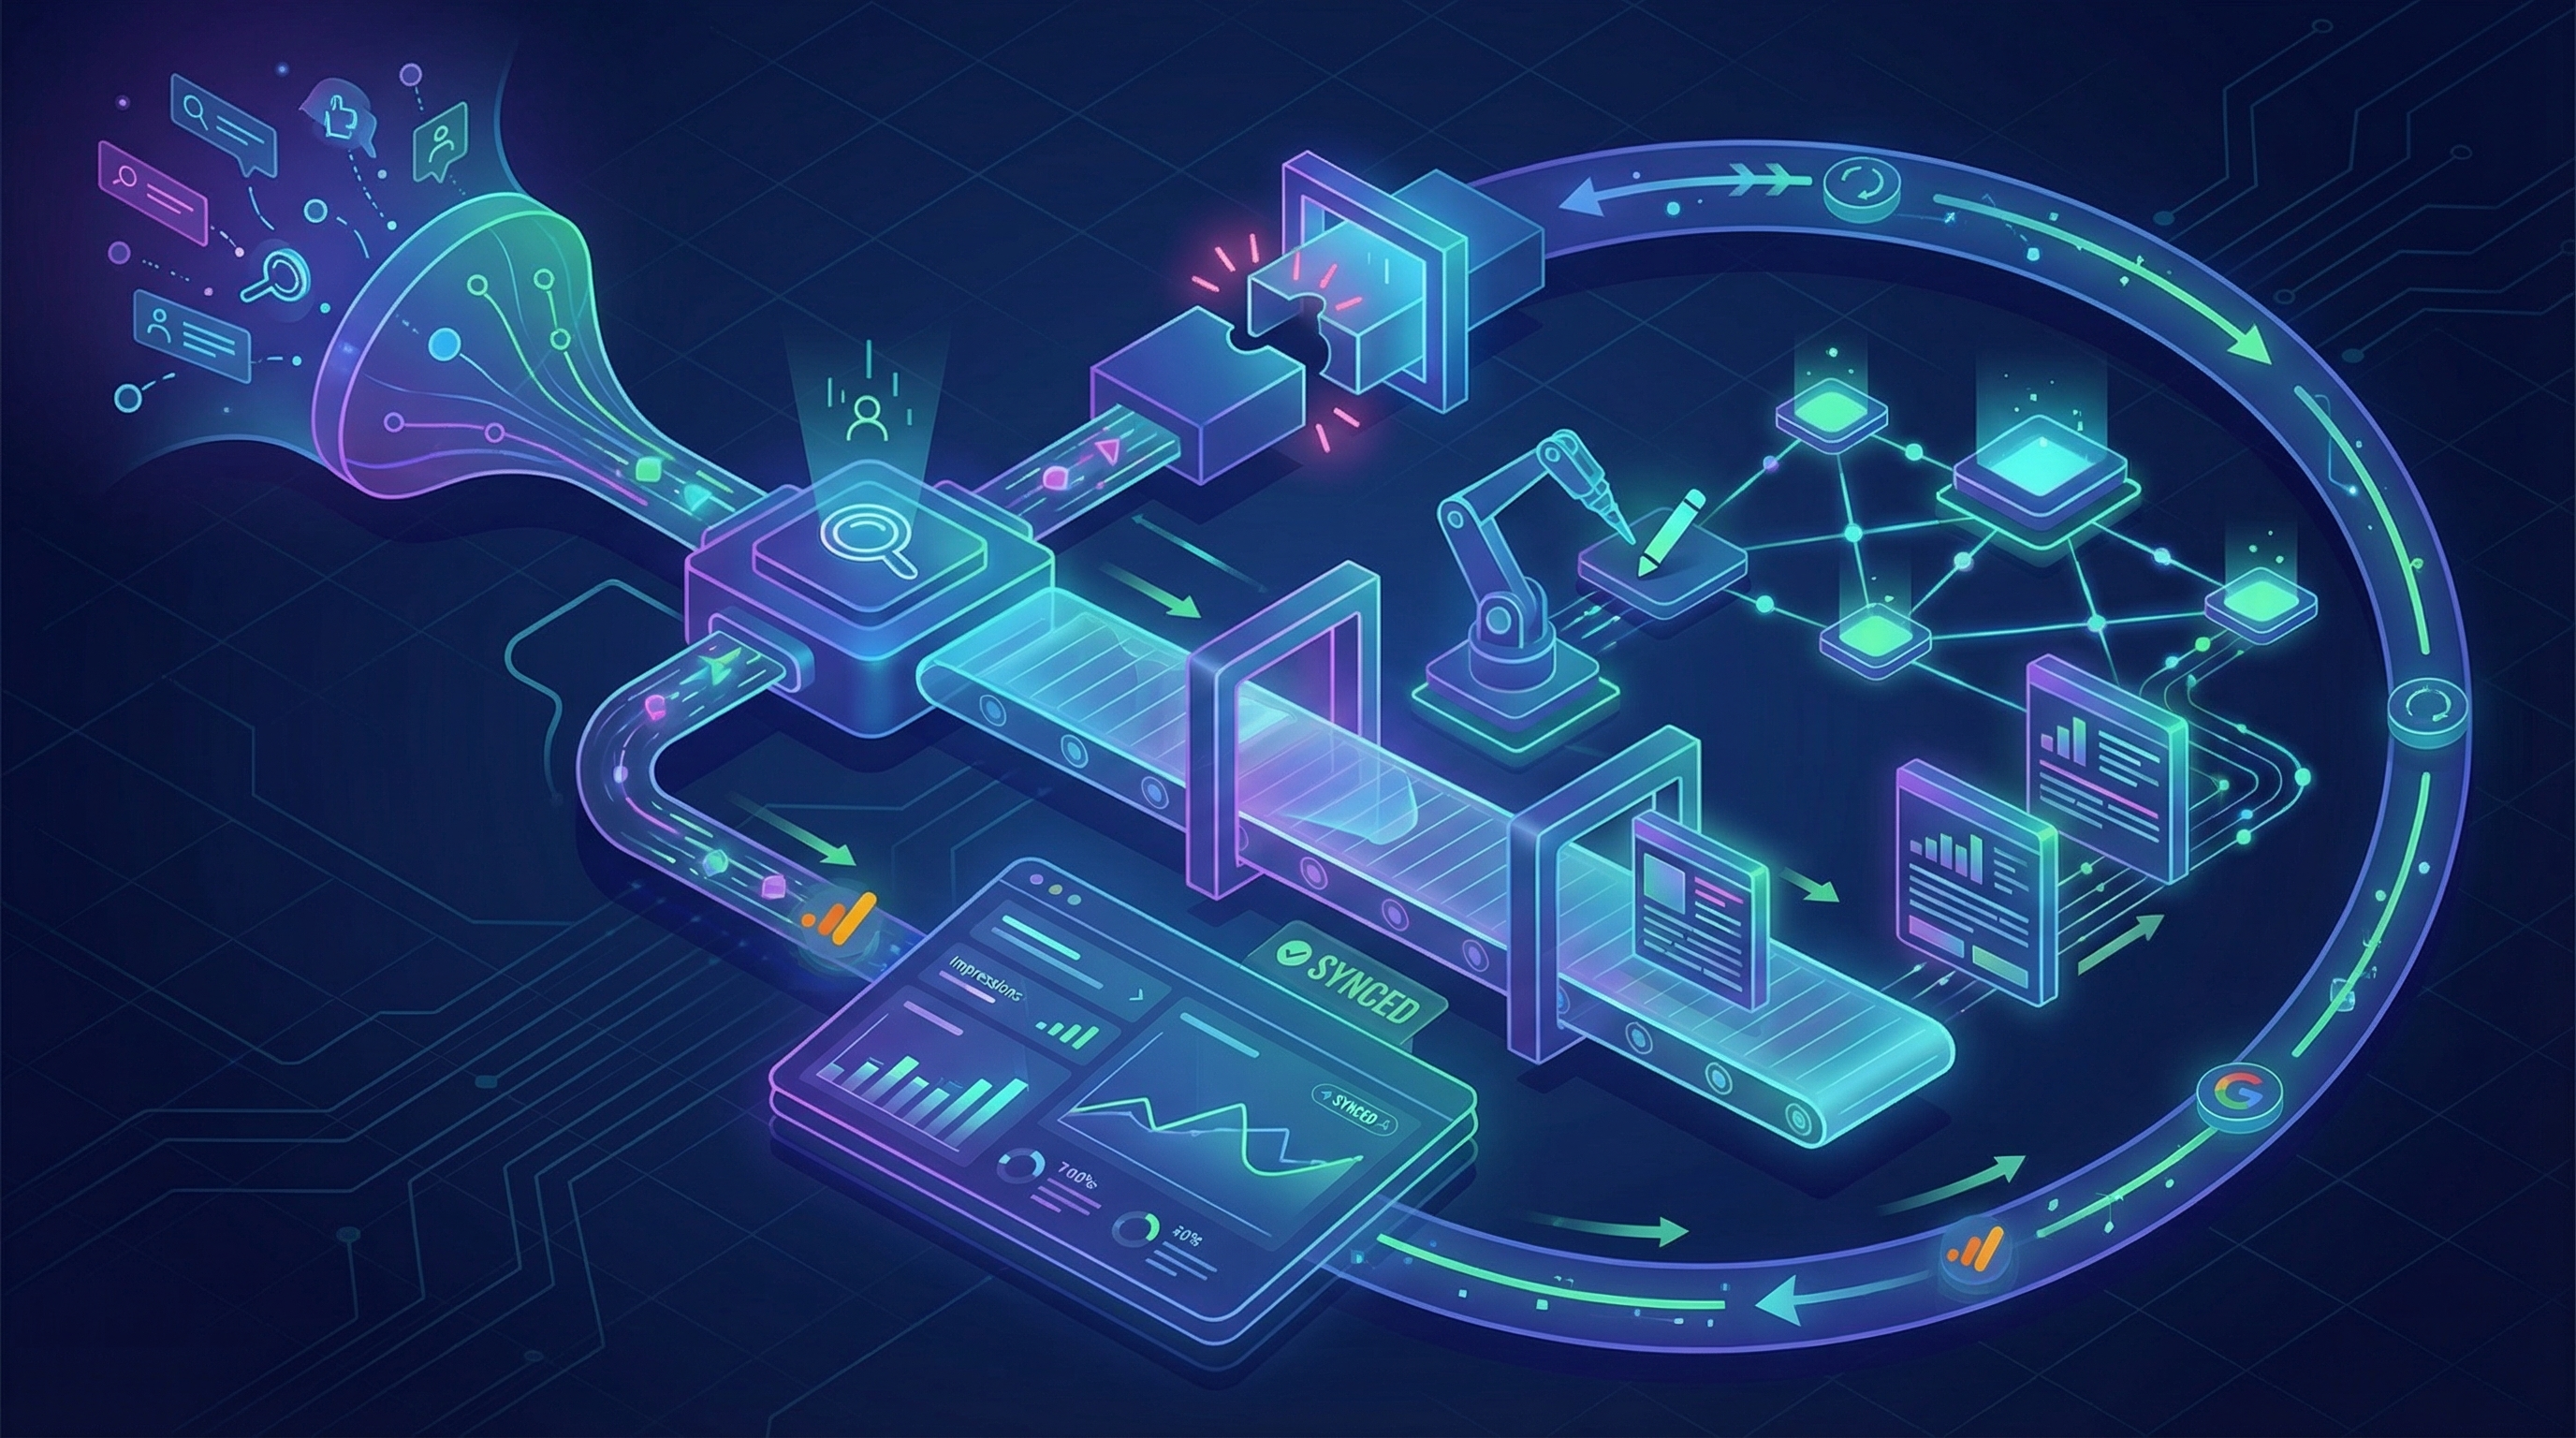
End-to-end architecture: competitor monitoring feeds gap detection, gap detection triggers brief generation, brief generation initiates content creation, content creation routes to publishing, publishing triggers rank tracking, rank tracking feeds back into gap scoring. Every stage connects to the next. No human handoff required between them. Learn more about Find Content Gaps Without Manual Keyword Research.
The operator's role in this system is configuration and oversight — not execution. You set the rules, define the competitor set, calibrate the scoring model, and review outputs at the quality gate. The system handles the rest. See how it works — this is what fully autonomous SEO looks like in practice. Learn more about Automate Keyword Discovery for Large Sites.
This is SEO that runs itself. Not because there's no strategy involved — the strategy is embedded in the system configuration. But because the recurring execution work has been removed from the human workload entirely. Learn more about Automate Keyword Research & Content Briefs.
Building the Pipeline: What Each Stage Actually Requires
Understanding the architecture conceptually is one thing. Knowing what it takes to make each stage production-ready is another. Here's what operators who've successfully closed the loop have actually built.
Competitor monitoring needs to run continuously, not weekly. The operators winning on velocity are detecting newly published competitor pages within 24–48 hours of indexation — not after their next scheduled crawl. This requires either a purpose-built monitoring layer or a platform that watches competitor sitemaps and indexed page counts in near real-time.
Gap scoring is where most systems break down. Surfacing a gap is easy. Scoring it correctly — weighting by search volume, keyword difficulty, topical authority proximity, and existing content cannibalization risk — is what separates a useful queue from a noisy one. Your scoring model needs calibration against your specific domain's competitive position, not generic industry benchmarks.
Brief generation has to encode your editorial standards, not generic SEO best practices. If the brief doesn't reflect your target reading level, internal linking priorities, content structure preferences, and brand voice parameters, every piece of content that flows from it will require human correction downstream — and you've reintroduced the handoff you were trying to eliminate.
Quality gates are non-negotiable in a fully autonomous system. Rather than having humans review every output, high-performing pipelines use automated scoring against defined criteria — factual consistency checks, structure validation, minimum topical depth thresholds — to route content either directly to publishing or to a human review queue. The goal isn't zero human involvement; it's human involvement only where judgment genuinely adds value.
Feedback loops are what make the system compound over time. When rank tracking data flows back into gap scoring, the system learns which content types and keyword patterns perform on your specific domain. This means the pipeline becomes more accurate and efficient the longer it runs — a structural advantage that manual workflows can never replicate, because human teams don't systematically learn from their own output at scale.
The operators building this in 2026 aren't waiting for a single platform to solve all of it. They're connecting specialized tools via API, defining clear data schemas between stages, and treating the pipeline itself as a core business asset.
The Bottom Line
Keyword research automation for content gaps isn't a tool feature — it's a system architecture decision. The operators winning in organic search right now aren't working harder on gap analysis; they've built pipelines that do it continuously, act on it automatically, and feed performance back into the loop.
Whether you're running an agency with 30 client sites or a SaaS founder trying to drive organic growth without a content team, the leverage is identical: stop manually hunting for gaps and build the system that hunts for you. Define your competitor set. Configure your detection rules. Route outputs into a publishing pipeline. Close the loop with rank tracking. Then let it run.
The sites compounding their organic traffic in 2026 stopped babysitting their content gap audits. They built the system once and let it do the work. If your current process still depends on someone opening a spreadsheet to find opportunities, that's the bottleneck worth fixing — and it's fixable. See how Ranklynk's autonomous SEO engine handles gap discovery, content creation, and publishing in one closed loop — no spreadsheets, no manual handoffs, no babysitting required. See how it works.
Frequently Asked Questions
Q: What is keyword research automation for content gaps?
Keyword research automation for content gaps is a systematic process where software continuously monitors competitor keyword rankings, cross-references them against your own domain's keyword universe, and automatically identifies topics your site is missing — without requiring manual effort each time. Unlike traditional gap analysis, which involves manually exporting spreadsheets and color-coding competitor data, automated systems run on their own schedule. They detect new competitor rankings, score identified gaps by opportunity, and can route actionable topics directly into your content pipeline. The core goal is to close the delta between what your competitors rank for and what you don't — and to do it faster than your competitors can respond.
Q: Why is manual content gap analysis a problem for growing SEO teams?
Manual content gap analysis breaks down quickly at scale because gaps are dynamic, not static. Competitors publish new content clusters regularly, creating dozens of new ranking opportunities overnight. If your team only runs quarterly or monthly audits, you're already weeks or months behind by the time you act. For agencies managing 10 or more domains, a thorough manual gap audit takes 4–8 hours per domain. That adds up to 80–160 hours per month just to maintain the process — equivalent to a full-time hire before a single piece of content is produced. The hidden opportunity cost is just as damaging: gaps identified in real-time can be acted on before competitors consolidate rankings, while delayed discovery means missed traffic you can never recover.
Q: What is the difference between semi-automated and fully automated keyword gap workflows?
Semi-automated keyword gap workflows still require human involvement at key stages — you might pull reports automatically, but an analyst still interprets the outputs, filters the data, and manually assigns content tasks. Fully automated workflows eliminate the human trigger entirely. In a fully automated system, the pipeline continuously crawls competitor rankings, detects new gaps, scores them against predefined opportunity thresholds, and routes briefs directly into your content production queue — all without an analyst in the loop. For small teams or single-domain operators, semi-automation may be sufficient. For agencies or high-volume content operations, full automation is the difference between a tool that makes you faster and a system that generates results while your team focuses on higher-value work.
Q: How does keyword research automation for content gaps actually work technically?
The technical pipeline for automated content gap analysis consists of four core stages: data ingestion, gap detection, prioritization, and routing. Data ingestion involves continuously pulling competitor ranking data and your own keyword universe from sources like SEO APIs or rank tracking tools. Gap detection cross-references those datasets to surface keywords competitors rank for that your domain does not. Prioritization applies scoring logic — factoring in search volume, keyword difficulty, topical relevance, and business intent — to rank gaps by opportunity value. Finally, routing pushes the highest-priority gaps into your content workflow, whether that's a project management tool, a content brief generator, or an AI writing pipeline. When fully built, this system runs continuously on its own schedule rather than waiting for a human to trigger the process.
Q: At what point does manual keyword gap analysis become unsustainable?
Manual keyword gap analysis typically hits its scalability ceiling around 10 clients or domains. Below that threshold, recurring audits can feel manageable — time-consuming but doable. Above it, the process structurally breaks down. Prioritization decisions stop being driven by opportunity data and start being driven by whoever has the loudest client or the most urgent deadline. The compounding problem is that a monthly discovery cycle means every week of lag represents organic traffic that goes to a competitor instead. For agencies or in-house teams managing multiple properties, the real question isn't whether manual analysis is possible — it's whether the time investment makes financial and strategic sense when automated alternatives can surface the same data continuously and at a fraction of the ongoing cost.
Q: What are the main benefits of automating keyword research for content gaps?
The primary benefits of keyword research automation for content gaps include speed, scalability, and compounding organic growth. Speed matters because gaps identified in real-time can be acted on before competitors double down on those topics. Scalability matters because automated systems can monitor dozens of domains simultaneously without adding headcount. The compounding benefit is perhaps the most significant: an automated pipeline that continuously discovers and acts on gaps builds topical authority faster than any team doing the same work manually. Additional benefits include reduced analyst burnout, more consistent gap monitoring cadence, and data-driven prioritization that removes subjective judgment from the content planning process. Teams that automate this workflow free up their human resources for strategy, creative direction, and quality control rather than repetitive data wrangling.
Q: What common mistakes should teams avoid when setting up keyword gap automation?
One of the most common mistakes is treating automation as simply a faster version of a manual spreadsheet workflow — pulling the same reports faster without redesigning the underlying process. True keyword research automation for content gaps requires rethinking the entire pipeline from discovery to publication. Another mistake is failing to define clear opportunity scoring criteria before automating, which results in the system surfacing large volumes of low-quality or irrelevant gaps that still require heavy human filtering. Teams also frequently neglect to update their competitor set, allowing the system to monitor outdated or irrelevant domains. Finally, many operators automate discovery but leave prioritization and routing as manual steps, creating a bottleneck that undermines the efficiency gains. A well-designed system should handle all four stages — ingestion, detection, prioritization, and routing — with minimal manual intervention.
References
[1] https://seobotai.com/blog/ai-agents-in-seo-keyword-research-automation/. seobotai.com. https://seobotai.com/blog/ai-agents-in-seo-keyword-research-automation/
[2] https://www.semrush.com/blog/content-gap-analysis/. semrush.com. https://www.semrush.com/blog/content-gap-analysis/
[3] https://searchengineland.com/guide/gap-analysis. searchengineland.com. https://searchengineland.com/guide/gap-analysis
[4] https://www.singlegrain.com/artificial-intelligence/automated-keyword-research-with-ai-to-uncover-hidden-gems/. singlegrain.com. https://www.singlegrain.com/artificial-intelligence/automated-keyword-research-with-ai-to-uncover-hidden-gems/
[5] https://www.factors.ai/blog/niche-keyword-research-guide. factors.ai. https://www.factors.ai/blog/niche-keyword-research-guide