How to Publish 100 AI Articles Per Month Systematically (Without Burning Out Your Team)
Most content teams hit a ceiling at 10–15 articles per month. The ones publishing 100+ aren't working harder — they've built a system that runs without them.
Publishing at scale used to mean hiring armies of writers, editors, and SEO managers. In 2026, the constraint isn't headcount — it's whether you've engineered a repeatable, automated pipeline from keyword discovery to published URL. The agencies and founders who cracked this aren't using AI as a writing assistant. They've turned their entire content operation into a closed-loop machine.
This guide breaks down exactly how to build a systematic pipeline that outputs 100 AI-generated, SEO-optimized articles per month — with minimal human intervention, zero guesswork, and infrastructure that compounds over time. Whether you're an agency owner managing a dozen client sites or a solo SaaS founder trying to drive organic traffic without burning runway on content costs, the architecture is the same. The pipeline is the product.
Why Most AI Content Operations Fail Before They Scale
Here's the uncomfortable truth: most teams experimenting with AI content generation aren't running an AI content system — they're running a more expensive version of their old content process. Someone still opens a doc. Someone still pastes in a keyword. Someone still edits line by line. The AI sped up the writing. It didn't eliminate the bottleneck.
Research consistently shows that approximately 85% of AI projects fail — and the culprit is almost never the technology [1]. It's the absence of process architecture. There's no repeatable workflow. No defined inputs and outputs. No quality gates that run without a human standing in the doorway. The result is random content generation: articles produced when someone has time, optimized when someone remembers, and published when someone finally gets to it.
That's not a system. That's a content backlog with an AI subscription bolted on.
Systematic means something specific: repeatable inputs producing predictable outputs. Every time a keyword enters the queue, the same chain of events fires — brief generation, draft creation, on-page SEO injection, formatting, and publishing — without reinvention. No meetings about what to write next. No approval chains that stall a perfectly good draft for two weeks.
The 3 C's of a Scalable AI Content System
The operators running 100-article months have internalized three properties that separate a system from a tool:
Consistency means the same workflow runs every time without reinvention. It doesn't matter if it's article number three or article number three hundred — the process is identical. Consistency is what makes quality predictable at volume.
Coverage means your keyword universe is fully mapped and queued, not cherry-picked based on what someone found interesting this week. Every topic cluster has assigned articles. Every piece of content has a defined place in the architecture before a single word is generated.
Compounding means published content feeds back into the discovery engine. New rankings surface new keyword gaps. New gaps populate the queue. The system learns from its own output and gets more efficient over time — not because anyone is manually analyzing it, but because the feedback loop is built in.
Why Volume Without Structure Destroys SEO
Publishing 100 thin, disconnected articles is worse than publishing 10 authoritative, cluster-mapped ones. Volume is an accelerant — it amplifies whatever structure (or lack of structure) exists underneath it. Without topical authority architecture, you're generating signal noise that Google's helpful content systems are specifically engineered to discount [2].
Quality thresholds must be baked into the system, not applied manually after the fact. Systematic does not mean spammy — it means the rules that define helpfulness, depth, and E-E-A-T compliance are encoded into the pipeline itself, not dependent on a human reviewer catching problems before they go live.
Step 1 — Build Your Keyword Pipeline (The Feed That Powers Everything)
Your keyword list is your production queue. Treat it like one. Most teams manage keywords like a wishlist — a spreadsheet someone added to when they had a good idea. That approach collapses at 100 articles per month because there's no structured intake, no prioritization logic, and no automatic replenishment.
The correct model is a segmented, auto-refilling queue. Keywords enter the queue through three primary sources: programmatic research via SEO APIs (pulling volume and difficulty at bulk), competitor gap analysis (identifying URLs your competitors rank for that you don't), and PAA (People Also Ask) extraction that surfaces long-tail informational intent at scale [3]. Every keyword is tagged at intake: search intent, difficulty tier, topical cluster assignment, and commercial priority score. No keyword enters the generation queue without those attributes populated — because those attributes drive every downstream decision about structure, depth, and linking.
The evergreen queue model means that as articles are published and keywords are consumed, the queue auto-refills based on pre-defined discovery rules. The pipeline never runs empty. The machine never waits for a human to decide what to write next.
Mapping Topical Authority at Scale
Publishing 100 random articles underperforms 100 cluster-mapped articles by a significant margin. Topical authority is the compounding asset here — Google rewards sites that demonstrate deep, systematic coverage of a subject area. A hub-and-spoke architecture operationalizes this: pillar pages cover the broadest topic, satellite content addresses every sub-question, and the internal linking structure signals the relationship between them.
At 100 articles per month, you can't manually assign every piece to its cluster. Cluster assignment must be automated — every keyword gets tagged to its hub at intake, every generated article receives its internal linking instructions from that tag, and the architecture self-reinforces with every publish. This is how 100 articles builds authority instead of diluting it.
Step 2 — Systematize Content Generation Without Babysitting Every Output
The single most expensive habit in AI content operations is treating AI as a writing assistant instead of a generation engine. Writing assistants require a human in the loop for every output. Generation engines run batch jobs and deliver publish-ready drafts on schedule.
The 30% rule applies here: human judgment should represent roughly 30% of the total effort in a well-built system, and that 30% should be concentrated entirely on strategy and structure — not line-by-line editing. If you're reading every AI draft before it publishes, you've built a content review operation, not a content system.
Prompt engineering is infrastructure, not a task. A well-architected prompt library is built once and deployed at scale. Templated content briefs standardize H2 structure, target word count, tone calibration, internal linking rules, and citation requirements. Every article generated from the same cluster template produces structurally consistent output — which means quality control can happen at the template level, not the individual article level [2].
Batch generation versus drip generation is an operational choice. Batch models generate a week's worth of content in a single pipeline run, then schedule publishing across the week. Drip models generate one article per day on a rolling basis. Both work — the right choice depends on your CMS architecture and how you manage scheduling logic.
Building Prompts That Output Publish-Ready Drafts
A high-yield content prompt isn't a keyword and a word count. It's a structured input that encodes everything the generation engine needs to produce a publishable output: the target keyword, search intent classification, top competitor context, brand voice parameters, structural rules (specific H2 requirements, FAQ inclusion, schema type), and E-E-A-T enforcement signals.
Generic prompts produce generic content. The fix isn't better writing — it's better prompt architecture. Version-control your prompt library the same way engineers version-control code. When a prompt produces a quality regression, you identify the variable, update the template, and the fix propagates across every future article in that cluster. Quality improves systematically, not article by article.
The 10-20-70 Rule Applied to AI Content Operations
Think of your 100-article operation as a resource allocation problem:
10% — Strategy and Architecture (human-led): Keyword universe definition, cluster architecture, template design, and brand voice encoding. This is where human judgment creates the most leverage. Decisions made here govern thousands of downstream outputs.
20% — Quality Control and Optimization Rules (semi-automated): Rule-based QA gates that check for structural completeness, minimum word count compliance, internal link presence, and schema injection. These gates run programmatically — human review only triggers on flagged exceptions, not standard outputs.
70% — Generation, Formatting, and Publishing (fully automated): The engine runs. Keywords enter, drafts generate, on-page SEO is injected, formatting is applied, and content is pushed to the CMS. No manual steps. No queue of drafts waiting for someone to hit publish.
Step 3 — Automate Publishing, Formatting, and On-Page SEO
Drafts sitting in Google Docs are a publishing velocity killer. Every manual step between generation and live URL is a failure point — and at 100 articles per month, those failure points compound into backlogs that stall the entire operation.
The publish stack needs to eliminate manual uploads entirely. CMS integrations — whether WordPress REST API, Webflow CMS API, or a headless CMS layer — should receive formatted content directly from the generation pipeline and push to published status based on the schedule logic, not based on someone clicking a button [4].
Automated on-page SEO means meta titles, meta descriptions, schema markup, and internal link injection all happen at publish time, not as a separate task. Image sourcing follows defined rules — stock library API calls, alt text generated from keyword context, file naming conventions applied automatically. The article that reaches the live URL is already fully optimized. There's nothing left to do.
The Publish Stack: Tools That Eliminate Manual Steps
Headless CMS architectures (Contentful, Sanity, Payload) offer cleaner API surfaces for high-volume publishing than traditional WordPress setups, though WordPress with REST API and the right automation layer works effectively at scale. The key architectural decision is webhook-driven workflows: content generation triggers a formatting step, which triggers CMS upload, which triggers indexing requests, which triggers rank tracking initialization. The entire chain fires without a human touching it.
Quality control at volume requires rule-based gates, not human review queues. Define your quality criteria programmatically: minimum word count, required H2 count, internal link presence, keyword density range, schema type inclusion. Articles that pass all gates proceed to publish automatically. Articles that fail get flagged for exception review — which should represent a small minority of output if your prompt architecture is solid.
If you want to see exactly how a pipeline like this runs end to end, see how it works — from keyword intake to live, indexed URL without manual intervention.
Step 4 — Build Continuous Optimization Into the System (Not a Monthly Review)
Publishing 100 articles is the beginning of the operation, not the finish line. Most teams treat publishing as the end state — the article goes live, the task closes, and that URL is never touched again unless someone notices it underperforming months later during a quarterly audit. That's the publish-and-pray pattern, and it's one of the primary reasons high-volume content operations fail to generate compounding returns.
The system handles optimization continuously. Automated rank tracking monitors every published URL and flags positions that cross defined thresholds — dropping below page two, losing more than X% traffic week-over-week, or failing to rank for the target keyword within 90 days. These flags automatically queue the article for a content refresh job: the system pulls current ranking data, competitor content analysis, and updated keyword context, then generates an optimized revision without a human initiating the process [5].
Stopping the 'Publish and Pray' Pattern
Content decay is a predictable phenomenon. Articles that ranked well at six months will lose ground to fresher, more comprehensive competitors at twelve months if left untouched. The teams that compound their authority are the ones that detect decay automatically and refresh systematically — not the ones that schedule quarterly content audits that never happen because everyone's busy publishing new content.
Automated refresh triggers remove the dependency on human memory. When a URL crosses a decay threshold, it enters the refresh queue. The refresh job runs on the same pipeline architecture as new content generation — same prompt templates, same quality gates, same CMS integration. The only difference is the input: instead of a new keyword, the input is the existing article plus the performance context that explains why it needs updating.
This is the compounding advantage: a self-optimizing content library that grows in authority and coverage without requiring additional headcount to maintain it. The system audits itself. The pipeline repairs its own outputs.
Operational Architecture: How to Actually Run This at 100 Articles Per Month
The weekly operating rhythm of a 100-article-per-month machine is radically different from a traditional content operation. There are no editorial meetings. No writer briefings. No "what are we publishing this week" discussions. The keyword queue dictates the schedule. The pipeline executes it.
In a fully built system, the human roles that remain are: one person monitoring the system dashboard for exception flags, one person maintaining and improving the prompt library, and one person handling strategic decisions about cluster expansion and audience targeting. That's it. Three part-time functions managing an operation that would have required a team of fifteen in 2022.
The metrics that matter are not vanity metrics. Total articles published per month is an input metric. What matters is: indexed URL count, average ranking position by cluster, organic traffic growth rate, and content decay rate (the percentage of the library that has dropped below ranking thresholds and queued for refresh). A healthy system shows declining decay rates and rising average positions over time — the compounding signal that the architecture is working.
How Agencies Are Running This Across Multiple Client Sites
The architecture described above is client-agnostic by design. One pipeline, multiple output configurations. Each client site has its own keyword universe, brand voice parameters, cluster architecture, and CMS integration — but all of them run through the same generation and publishing infrastructure. Adding a new client doesn't mean rebuilding the system. It means configuring a new parameter set and initializing a new keyword queue.
Reporting automation means clients see ranking progress, content output metrics, and traffic growth without you manually pulling data from five different tools and formatting a deck. The reporting layer runs on the same data pipeline that powers the content operation. Results are visible in real time. The relationship becomes about strategic direction — not status updates.
For agencies specifically, this model changes the unit economics of content delivery. When 70% of production is fully automated, you're no longer pricing by the article or the hour. You're pricing the system — and the system scales without proportional cost increases.
Frequently Asked Questions
What is the 30% rule for AI content? The 30% rule means human input should govern strategy and structure — not line-level editing — representing roughly 30% of total effort in a well-built AI content system. The remaining 70% is handled by automated generation, formatting, and publishing workflows.
What is the 10-20-70 rule for AI? 10% is human-led strategy and architecture (keyword universe, cluster design, prompt engineering). 20% is semi-automated quality control and optimization rule configuration. 70% is fully automated generation, formatting, and publishing — the part of the system that runs without you.
Why do 85% of AI projects fail? Lack of process architecture and clear ownership — not lack of technology [1]. Most teams have access to capable AI tools. The failure point is the absence of a repeatable workflow that defines exactly what enters the system, how it's processed, and what exits it.
How do you publish 50–100 human-like AI articles per month? Systematic prompt engineering that encodes brand voice and structural rules, cluster-mapped keyword queues that auto-refill, automated publishing pipelines with CMS integrations, and built-in E-E-A-T signals (author schema, source citations, first-person data layers) applied programmatically at generation time.
What are the 3 C's of AI content systems? Consistency, Coverage, and Compounding — the three properties that separate a scalable content system from a collection of AI tools. Consistency makes quality predictable. Coverage ensures topical authority builds systematically. Compounding means the system improves without additional human input over time.
The Bottom Line
Publishing 100 AI articles per month isn't a content volume problem — it's a systems architecture problem. The operators winning at scale didn't hire more writers. They stopped babysitting their content pipeline and built a machine that handles keyword discovery, generation, publishing, and optimization without manual intervention.
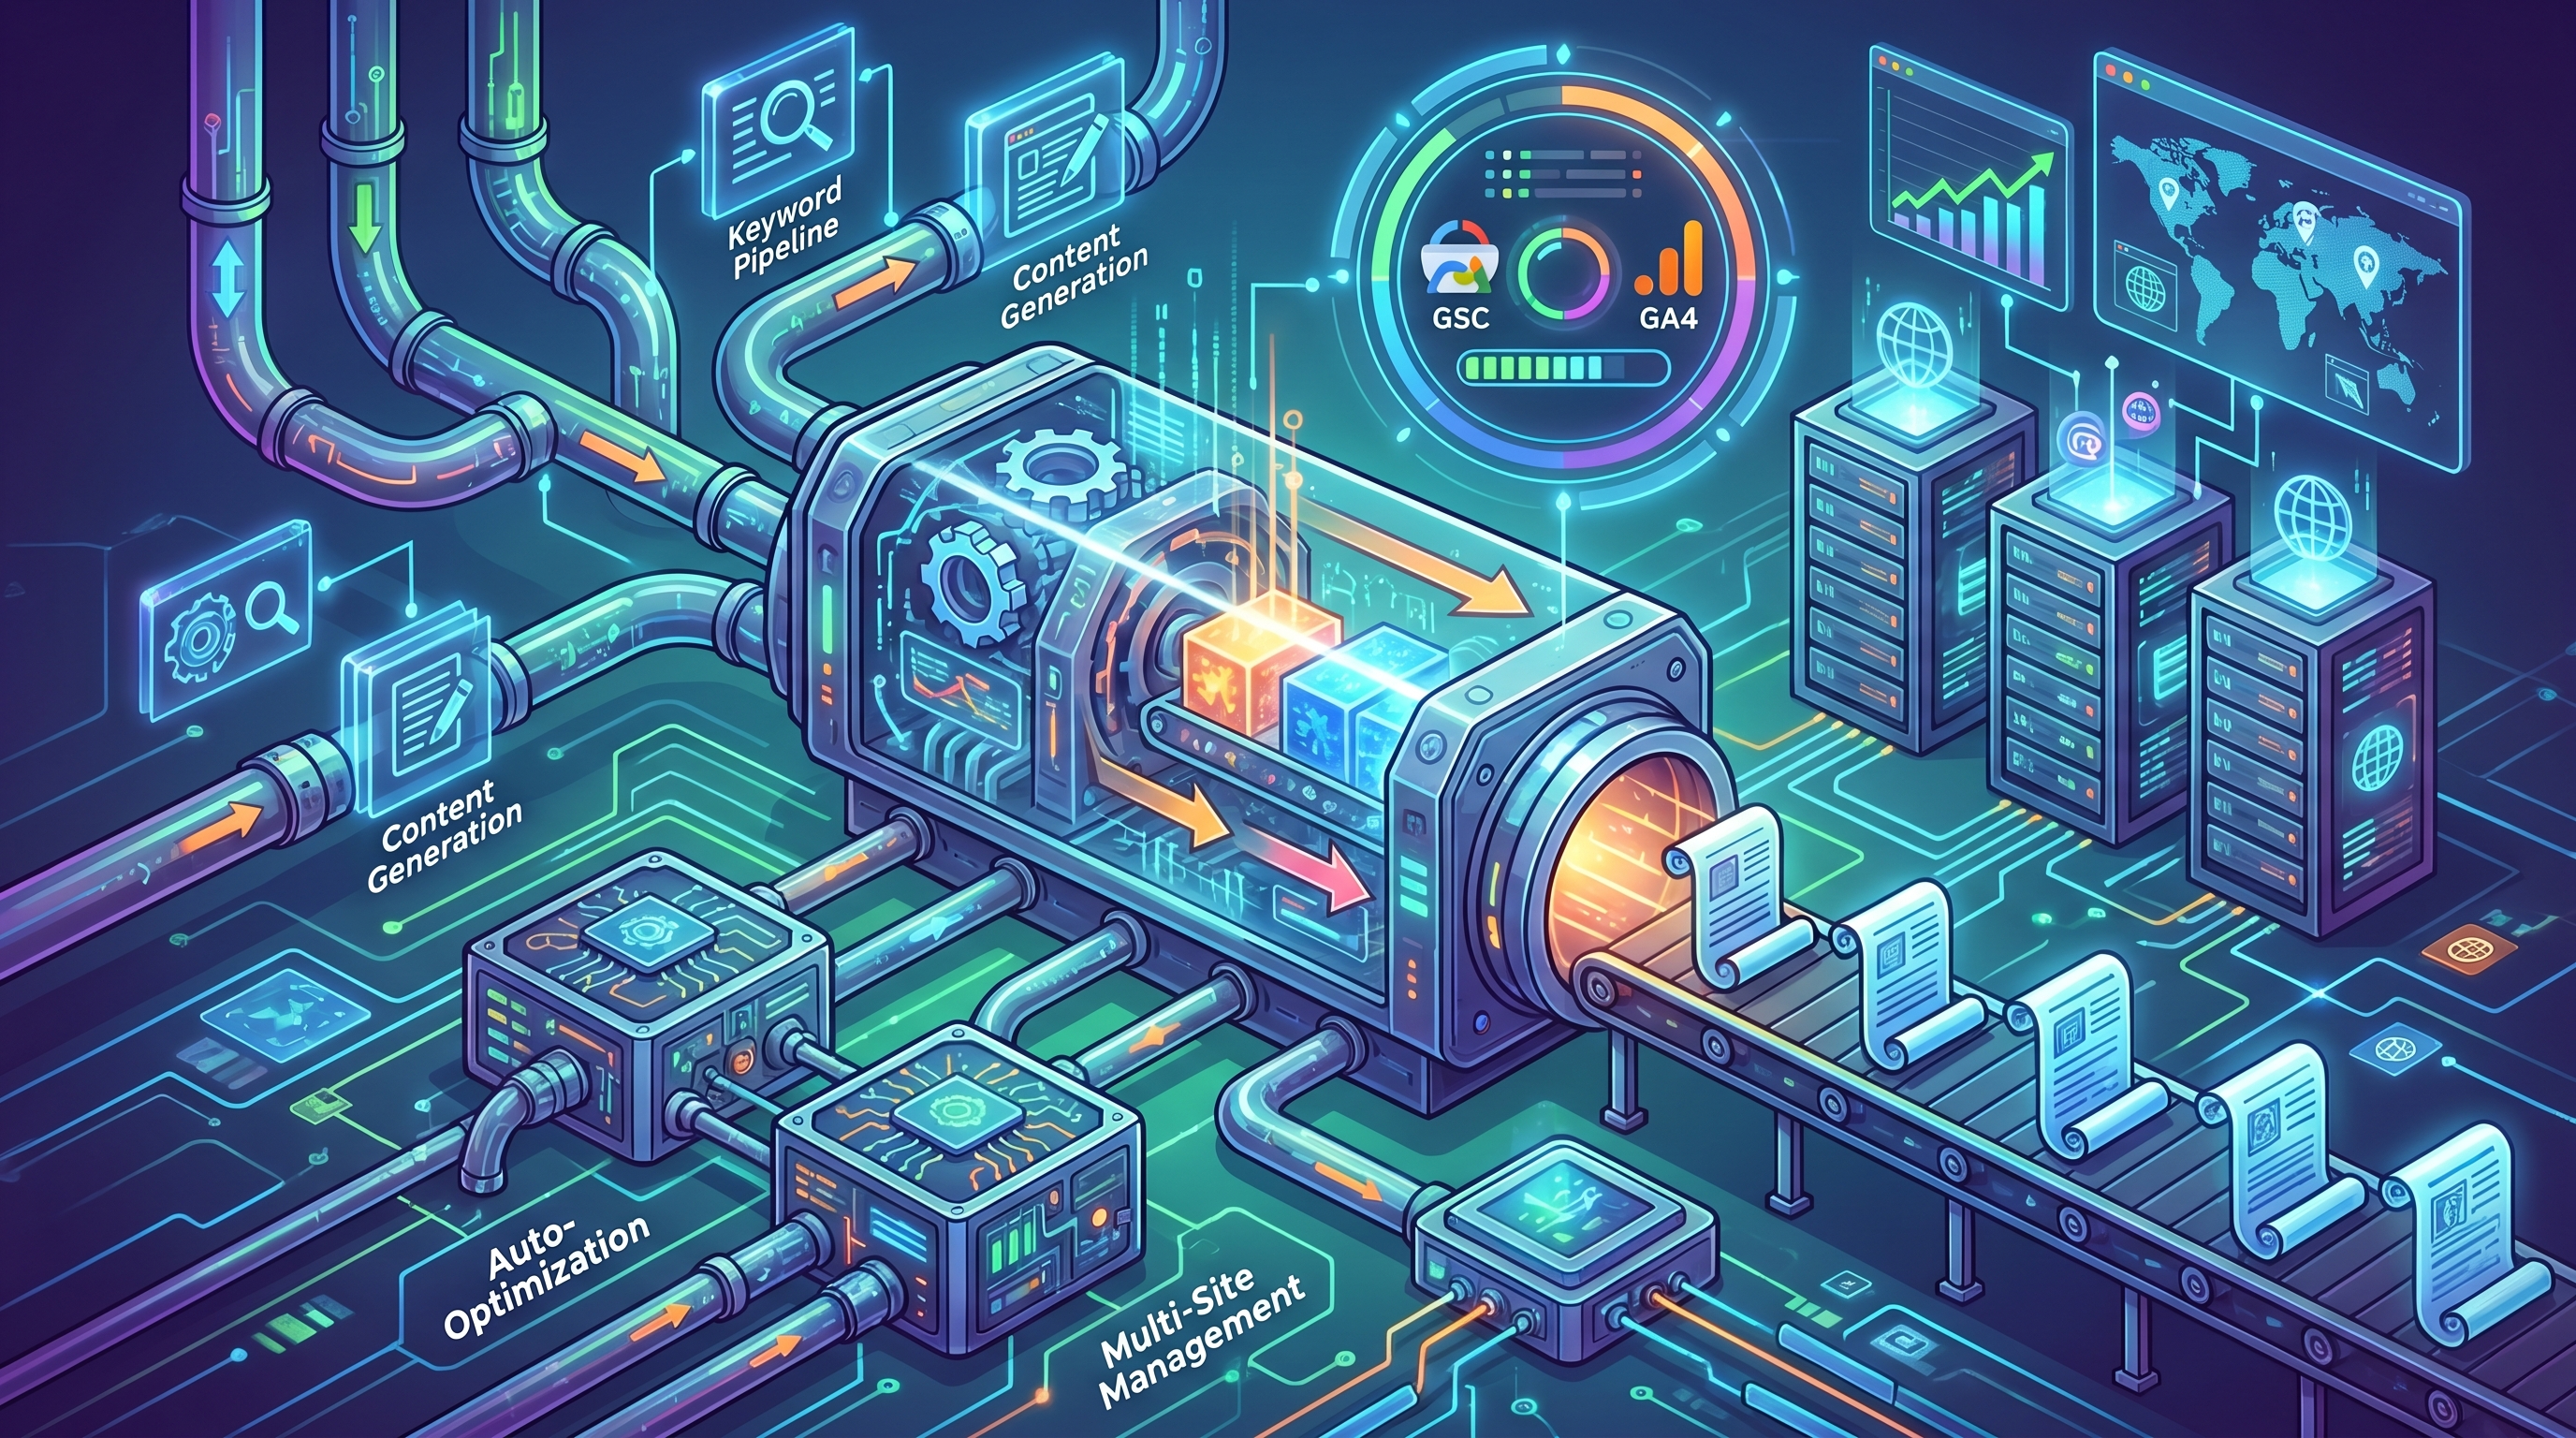
Every component described in this guide is interconnected: the keyword queue feeds the generation engine, the generation engine feeds the publish stack, the publish stack feeds the rank tracker, and the rank tracker feeds back into the keyword queue. That's a closed loop. That's what compounds.
The teams still managing content manually — still scheduling editorial meetings, still reviewing every draft, still manually pulling audit reports — aren't just slower. They're structurally incapable of competing with operations that have built the machine. The gap widens every month the system runs.
The pipeline is the product. Once it's running, it compounds. If you're ready to stop rebuilding your content process from scratch every quarter, see how Ranklynk runs the entire pipeline — from keyword discovery to published, optimized content — without you in the loop.
Frequently Asked Questions
Q: What is the 30% rule for AI?
The 30% rule for AI content refers to the widely recommended practice of spending roughly 30% of your total content production effort on human review, editing, and quality assurance — while allowing AI to handle the remaining 70% of the heavy lifting. In the context of publishing 100 AI articles per month systematically, this means your team is not rewriting every draft from scratch but instead reviewing for accuracy, brand voice alignment, factual correctness, and SEO intent matching. The 30% human-touch threshold helps maintain content quality at scale without creating the bottleneck that kills most AI content pipelines. Teams that ignore this rule either over-edit (slowing output to a trickle) or under-edit (publishing low-quality content that damages domain authority). Building the 30% review stage into your workflow as a defined, time-boxed step — rather than an open-ended editing session — is what allows a small team to sustain 100+ article months without burnout.
Q: What is the 10 20 70 rule for AI?
The 10-20-70 rule for AI content production is a resource allocation framework that guides how teams should divide effort across the three stages of a scalable content pipeline. 10% of effort goes into strategy and inputs — keyword research, topic clustering, and brief creation. 20% goes into AI generation, prompting, and initial draft output. The remaining 70% — the largest investment — goes into distribution, optimization, publishing, and compounding: internal linking, on-page SEO, schema markup, promotion, and performance monitoring. This rule is particularly relevant when learning how to publish 100 AI articles per month systematically, because it reframes AI writing as just one small step in a larger pipeline. Most teams get this backwards — they spend 70% of their time generating and editing content, then rush distribution. The 10-20-70 framework forces teams to build infrastructure around publishing and promotion, which is where long-term SEO compounding actually happens.
Q: Why do 85% of AI projects fail?
Research consistently shows that approximately 85% of AI projects fail, and the root cause is almost never the technology itself. The failure point is process architecture — or the complete lack of it. Most teams adopt AI tools as a faster version of their existing workflow rather than engineering a fundamentally new system. Someone still opens a blank document, pastes in a keyword, waits for a draft, then edits it line by line. The AI accelerated one step but left every other bottleneck intact. Systematic AI content production fails when there are no repeatable workflows, no defined inputs and outputs at each stage, and no automated quality gates. Without these, output is unpredictable — articles get published when someone has time, optimized when someone remembers, and reviewed when the backlog forces it. To avoid joining the 85%, teams need to treat their content pipeline as a product: documented, testable, and capable of running without constant human intervention at every step.
Q: How do we use AI to publish 50+ human-like articles per month?
Publishing 50 or more human-like articles per month with AI requires building a closed-loop pipeline rather than using AI as a one-off writing assistant. The process starts with a fully mapped keyword queue — every topic cluster researched, prioritized, and staged in advance so there are never decisions to make mid-production. From there, automated brief generation pulls in SERP data, competitor structure, and target intent signals. AI drafts are generated from structured prompts that embed brand voice, SEO requirements, formatting rules, and factual guardrails. A defined human review stage — capped at 20-30 minutes per article — handles fact-checking, tone adjustments, and intent validation. Finally, an automated publishing workflow handles on-page SEO injection, internal linking suggestions, schema markup, and CMS upload. The key to producing human-like output at scale is prompt engineering: the more context, structure, and constraints you give the AI, the less editing the draft requires. Teams hitting 50-100 articles monthly have invested heavily in their prompt library and brief templates — those assets are the real competitive moat.
Q: What are the 3 C's of AI content systems?
The 3 C's of a scalable AI content system are Consistency, Coverage, and Compounding — three properties that separate a true production system from a collection of AI tools. Consistency means the same workflow executes every time, regardless of whether it is article number three or article number three hundred. When the process is identical each time, quality becomes predictable at volume and human judgment is reserved for exceptions rather than reinvention. Coverage means your entire keyword universe is mapped, queued, and staged — not cherry-picked based on whatever someone found interesting that week. Full coverage ensures no topic cluster gaps and no wasted ranking opportunities. Compounding means each published article builds on the last through internal linking, topical authority, and cluster density — so the SEO value of article one hundred is exponentially greater than article one in isolation. Teams learning how to publish 100 AI articles per month systematically need all three C's working together. Missing any one of them caps your output, your quality, or your long-term organic growth potential.
Q: What is the 30% rule in AI content production?
The 30% rule in AI content production specifies that human editors and reviewers should account for no more than 30% of total production time per article. This boundary exists to protect scalability. When human review exceeds 30% of total effort per piece, the pipeline slows to a pace that no longer justifies the AI investment — you end up with the cost of AI tools plus the cost of a full editorial team. When human review drops below a meaningful threshold entirely, quality degrades and published content risks factual errors, brand voice inconsistencies, or thin SEO optimization. In practice, the 30% rule means setting a hard time cap on editing — typically 15-30 minutes per article — and using that window strategically for accuracy checks, intent alignment, and voice refinement rather than comprehensive rewrites. Teams that apply this rule when building systems to publish 100 AI articles per month find they can maintain consistent quality while keeping per-article production costs low enough to sustain the operation long-term.
Q: Which 3 jobs will survive AI in content production?
As AI handles more of the mechanical work in content creation, three roles have proven resilient and increasingly valuable in high-output publishing operations. First, the Content Strategist — someone who maps keyword universes, builds topic clusters, defines content goals, and sets the strategic direction that no AI can determine on its own. Strategy requires business context, competitive intelligence, and judgment that AI tools cannot replicate. Second, the Systems Architect or AI Operations Manager — the person who builds, maintains, and optimizes the content pipeline itself. Writing prompts, configuring automation workflows, auditing output quality, and improving the system over time is skilled technical and editorial work. Third, the Subject Matter Editor — someone with domain expertise who validates factual accuracy, adds proprietary insights, and ensures published content reflects genuine expertise rather than synthesized generalities. In operations built to publish 100 AI articles per month systematically, these three roles are not replaced by AI — they are amplified by it, with each person's output multiplied dramatically by the infrastructure they have built around them.
References
[1] https://guides.lib.purdue.edu/c.php?g=1371380&p=10592801. guides.lib.purdue.edu. https://guides.lib.purdue.edu/c.php?g=1371380&p=10592801
[2] https://www.trysight.ai/blog/bulk-content-creation-with-ai-step-by-step-guide. trysight.ai. https://www.trysight.ai/blog/bulk-content-creation-with-ai-step-by-step-guide
[3] https://hasanaboulhasan.medium.com/90-day-content-creation-challenge-how-im-using-ai-to-publish-100-pieces-monthly-part-1-56057a0426fd. hasanaboulhasan.medium.com. https://hasanaboulhasan.medium.com/90-day-content-creation-challenge-how-im-using-ai-to-publish-100-pieces-monthly-part-1-56057a0426fd
[4] https://falia.co/en/publishing-100-pages-at-once-on-a-new-website/. falia.co. https://falia.co/en/publishing-100-pages-at-once-on-a-new-website/
[5] https://spajonas.substack.com/p/the-100-book-reality-how-ai-makes. spajonas.substack.com. https://spajonas.substack.com/p/the-100-book-reality-how-ai-makes