Every piece of content your competitors are publishing, every chatbot answering customer questions, every search engine reranking its results — it all runs on the same underlying engine: AI language models. These systems have moved from research curiosity to operational backbone faster than most operators realize. If you are building products, running content pipelines, or making infrastructure decisions in 2026, you are already downstream of this technology whether you understand it or not.
In 2026, AI language models are the computational infrastructure of modern business [SOURCE_1]. But most people using them daily — or building products on top of them — still treat them as black boxes. That is a system-thinking failure. Understanding how these models work is not academic. It is the difference between deploying them strategically and prompting blindly, hoping for consistent output.
This guide breaks down what AI language models are, how they work, which ones matter, and how forward-thinking operators are already using them to automate workflows that used to require entire teams — including content and SEO at scale.
What Is an AI Language Model?
An AI language model is a statistical system trained to predict and generate human language. At its core, it learns patterns from enormous amounts of text. Then it uses those patterns to produce new text that is coherent, contextually relevant, and often surprisingly accurate [SOURCE_3].
The basic mechanic is called next-token prediction. Given a sequence of words, the model predicts the most likely next word — or more precisely, the next token. Repeat that process thousands of times and you get a paragraph, an article, or a line of code. The model is not retrieving stored answers. It is computing probabilities based on everything it learned during training.
Language models are distinct from other AI systems. Image models generate pixels, not words. Recommendation engines rank items by predicted preference. Language models operate on text — reading it, transforming it, and generating more of it. That specificity makes them uniquely powerful for any task that involves reading or writing at scale.
It is also worth separating the concept from the product. GPT-4o is a product. LLM architecture is the concept underlying it. ChatGPT is a consumer application built on top of an LLM — it adds a chat interface, safety layers, memory systems, and usage controls on top of the raw model [SOURCE_2]. The model alone is not the product. The product is the system built around it.
The Core Mechanic: How Language Models Actually Process Text
Text does not go into a language model as words. It gets broken into tokens first. A token is roughly a word or a word fragment. This matters because token limits, not word counts, govern what a model can process.
Tokens then become embeddings — numerical vectors that place each token in a high-dimensional space. Words with similar meanings cluster together in that space. This is how the model understands that 'car' and 'vehicle' are related without anyone telling it explicitly.
The attention mechanism is where the real intelligence happens. It lets the model weigh relationships between any two tokens in the input — regardless of how far apart they are. The word 'bank' in 'river bank' gets a different representation than 'bank' in 'savings bank' because attention pulls context from surrounding tokens [SOURCE_3].
For operators building on LLMs, these mechanics have direct implications. Context windows are defined in tokens. Output consistency depends on how well your prompt provides relevant context. Cost per API call scales with token count.
Language Model vs. Large Language Model: Is There a Difference?
Yes, and the distinction is useful. Early language models — n-gram models, RNNs, LSTMs — were functional but limited. They could not hold long-range context and did not scale gracefully with more data or compute.
The 'large' in LLM refers to parameter count: billions to trillions of learned numerical weights. Scale changed capability fundamentally. Behaviors that do not appear in small models — multi-step reasoning, code generation, analogical thinking — emerge past certain parameter thresholds [SOURCE_4].
The industry standardized on 'LLM' as the working term for transformer-based models with enough parameters to exhibit these emergent capabilities. When someone says 'LLM' today, they mean a modern, large-scale, transformer-based language model — not a simple autocomplete system.
What Is LLM and GPT? Understanding the Terminology
LLM stands for Large Language Model — the architectural category. GPT stands for Generative Pre-trained Transformer — a specific model family from OpenAI. GPT is one implementation of the LLM paradigm. It is not synonymous with all AI language models, even though most non-technical users treat those terms interchangeably.
Breaking down the GPT acronym clarifies what it actually describes. Generative means it produces new text. Pre-trained means it was trained on a massive general-purpose corpus before any task-specific adaptation. Transformer is the underlying neural architecture — the mechanism that makes modern LLMs possible [SOURCE_1].
The conflation of GPT with all AI matters for decision-making. If your team defaults to 'just use ChatGPT' for every LLM task, you are ignoring a landscape that includes Claude (Anthropic), Gemini (Google), Llama (Meta), Mistral, and dozens of specialized models — each with different strengths, costs, and constraints [SOURCE_5].
Transformers: The Architecture That Changed Everything
The 2017 paper 'Attention Is All You Need' introduced the transformer architecture. The core innovation was self-attention: a mechanism that lets every token attend to every other token simultaneously. That means the model can relate words at the beginning of a long document to words at the end — without processing them sequentially.
This was a leap over RNNs and LSTMs, which processed text one token at a time and struggled to retain context over long sequences. Transformers also parallelize during training, which means they scale with compute in a way older architectures could not. More GPUs, more data, more parameters — and performance kept improving [SOURCE_4].
For operators, the key takeaway is simple. LLMs are not databases. They do not look up answers. They compute outputs based on learned statistical patterns and the context you provide.
Pre-training vs. Fine-tuning vs. RAG: Three Layers of Model Behavior
Pre-training is the massive, general-purpose learning phase. A model is trained on hundreds of billions of words from the internet, books, and code. It learns grammar, facts, reasoning patterns, and style. Pre-training costs tens of millions of dollars. Only hyperscalers do it.
Fine-tuning takes a pre-trained base model and trains it further on curated data. You can fine-tune for instruction-following, domain-specific knowledge, or specific output formats. This is where most enterprise use cases operate — adapting a capable base model without building from scratch.
Retrieval-Augmented Generation (RAG) is different. Instead of retraining the model, RAG injects relevant documents into the model's context at inference time. You retrieve from a knowledge base, append the results to the prompt, and let the model generate a grounded answer. RAG solves the stale knowledge problem without retraining [SOURCE_3]. Most production knowledge-intensive applications — customer support bots, internal search tools, content research pipelines — run on RAG.
What Are the AI Language Models? A Taxonomy of the Ecosystem
The LLM landscape in 2026 is intentionally fragmented. There are closed-source frontier models, open-weight models, and specialized fine-tunes — each filling different roles in production systems.
Three primary tiers define the ecosystem. Frontier closed-source models (GPT-4o, Claude 3.5, Gemini 1.5 Pro) offer the highest capabilities but at API costs and with data-privacy constraints. Open-weight models (Llama 3, Mistral, Qwen) can be self-hosted, fine-tuned, and run without sending data to a third party. Specialized models handle narrow tasks — embedding, code generation, multilingual output — often better and cheaper than general-purpose frontier models.
In 2026, production systems commonly route across multiple models. A content pipeline might use an embedding model for semantic search, a frontier model for draft generation, and a smaller fine-tuned model for classification and tagging. Choosing a model is an infrastructure decision with cost, latency, and reliability implications — not a preference [SOURCE_5].
Closed-Source Frontier Models: GPT, Claude, and Gemini
OpenAI GPT-4o is multimodal, handles text and images in a single context window, and has the broadest tool integration in the API ecosystem. It remains the default choice for general-purpose LLM tasks where output quality is the primary constraint.
Anthropic Claude 3.5 Sonnet has a 200K-token context window and strong instruction-following. It is the preferred model for long-document tasks — contract review, research synthesis, long-form content generation.
Google Gemini 1.5 Pro runs natively inside Google Workspace and Search infrastructure. For teams already operating in the Google ecosystem, it is the model with the lowest friction and the deepest native integration. It also supports a 1M-token context window — the largest among frontier closed-source models.
Open-Weight Models: Llama, Mistral, and the Self-Hosted Stack
Meta Llama 3 is the most widely deployed open-weight model family in 2026. It runs on consumer hardware at the 8B parameter size and on enterprise infrastructure at 70B. Teams that need to fine-tune, self-host, or operate without sending data to third-party APIs default to Llama.
Mistral AI's models are fast, efficient, and strong across European regulatory environments where data residency requirements make third-party API calls a compliance problem. Mistral Large performs competitively with frontier models on multilingual tasks at a fraction of the API cost.
Open-weight wins when cost, volume, or compliance is the binding constraint. If you are running millions of inference calls per month, the difference between API pricing and self-hosted inference is significant. If your data cannot leave your infrastructure, open-weight is not optional — it is the only path.
Embedding Models and Specialized LLMs
Embedding models do not generate text. They convert text into numerical vectors for semantic search, similarity ranking, and RAG retrieval. Models like text-embedding-3-large (OpenAI) and Cohere Embed are purpose-built for this task and significantly outperform general-purpose LLMs when the task is retrieval, not generation.
Code-specialized models outperform general frontier models on narrow coding benchmarks at much lower cost per token. The operator's principle here is direct: use the smallest, cheapest model that reliably completes the task. Routing a code-generation subtask to a specialized model instead of GPT-4o can cut inference costs significantly with no quality loss on that specific task [SOURCE_5].
Is ChatGPT an LLM or Generative AI? Clearing Up the Confusion
ChatGPT is both — and distinguishing between the two terms matters for system design. Generative AI is the capability category: systems that generate new content — text, images, audio, video. LLMs are the text-specific subset of generative AI. ChatGPT is a generative AI application built on an LLM.
The product wraps the model in significant additional infrastructure. Safety layers filter inputs and outputs. Memory systems persist context across sessions. Plugin and tool infrastructure lets the model take actions. None of that is the LLM — it is the system built around the LLM.
This distinction has real operational consequences. The right question is not 'should we use ChatGPT?' It is 'which model, served how, with what retrieval layer and output validation, fits this task?' [SOURCE_1]
What Is the Best AI Language Model? The Operator's Framework
There is no universally best AI language model. There is only the best model for a specific task, at a specific cost constraint, with a specific latency requirement. Operators who chase benchmark leaderboards are optimizing for the wrong variable.
The evaluation framework that matters in production covers six dimensions: output quality on your actual task distribution, inference speed, cost per token, context window size, reliability and uptime, and fine-tuning availability. Each dimension interacts with the others. A model with a 1M-token context window is irrelevant if you cannot afford the compute cost at your query volume [SOURCE_4].
Top 5 Most Popular AI Models in 2026
The five most widely deployed AI language models in 2026 map to distinct use cases:
- GPT-4o (OpenAI) — dominant API ecosystem, broadest tool integration, strong default for general-purpose tasks across writing, reasoning, and multimodal inputs.
- Claude 3.5 Sonnet (Anthropic) — preferred for long-document tasks, instruction-following, and safety-sensitive production environments.
- Gemini 1.5 Pro (Google) — strongest for Google ecosystem integration, multimodal tasks, and applications requiring very large context windows.
- Llama 3 70B (Meta) — most widely deployed open-weight model, self-hosted and fine-tuned by enterprises and startups who need cost control or data privacy.
- Mistral Large (Mistral AI) — European enterprise favorite, strong multilingual performance, competitive pricing relative to frontier closed-source alternatives [SOURCE_5].
Usage patterns differ sharply by task type. Coding workflows skew toward GPT-4o and specialized code models. Long-document analysis skews toward Claude. SEO and content automation pipelines frequently route across multiple models — a frontier model for generation, an embedding model for retrieval, a smaller model for classification.
Why Are People Leaving ChatGPT? The Fragmentation Signal
Subscription fatigue is real. As Claude and Gemini closed the quality gap in 2025 and 2026, the cost-benefit math of a ChatGPT Plus subscription shifted. Teams paying for multiple AI subscriptions started consolidating — and not always around OpenAI.
Enterprise compliance is the other driver. Data residency requirements in regulated industries push teams toward self-hosted open-weight models or providers with stronger data processing agreements.
The macro signal is what matters for operators: the LLM market is fragmenting. No single model will dominate every use case. Teams that hard-code a single provider into their stack are building fragile systems. The operators who stay competitive are building model-agnostic pipelines that can route across providers as the landscape shifts.
How LLMs Are Trained: The Engineering Behind the Intelligence
Understanding the training pipeline helps operators set realistic expectations for model behavior. The pipeline has five stages.
Stage one is data collection and preprocessing. Models are trained on internet-scale text corpora — web crawls, books, code repositories, scientific papers. Data is filtered for quality, deduplicated, and formatted.
Stage two is pre-training. The model learns to predict the next token across billions of documents. No human labels — just scale. This is where the majority of the model's general knowledge and language capability is acquired. Training a frontier model costs tens of millions of dollars in compute [SOURCE_3].
Stage three is supervised fine-tuning (SFT). Human annotators create instruction-response pairs. The model is trained to follow instructions — to answer questions, complete tasks, and format outputs in useful ways.
Stage four is RLHF — Reinforcement Learning from Human Feedback. Human raters compare model outputs and rank them. A reward model is trained on those rankings. The LLM is then optimized against the reward model to produce outputs humans prefer.
Stage five is deployment infrastructure: quantization, serving optimization, and load balancing. This stage is what makes large models practical at scale.
Context Windows, Token Limits, and What They Mean for Your System
The context window is the amount of text the model can process at once during a single inference call. It is measured in tokens. GPT-4o supports 128K tokens. Claude 3.5 supports 200K. Gemini 1.5 Pro supports 1M. These are not arbitrary caps — they reflect memory and compute constraints in the underlying architecture.
Context window size directly determines what you can build. Long-document summarization, multi-turn conversation memory, large codebase reasoning — all of these require large context windows. If your task involves processing a 300-page document in a single pass, Claude or Gemini 1.5 Pro is your starting point.
The cost tradeoff is non-trivial. Every token in the context window costs compute at inference time. RAG architectures solve this problem by retrieving only the relevant chunks and injecting them into the context — keeping token counts manageable while maintaining access to large knowledge bases [SOURCE_3].
Hallucination, Bias, and Why LLMs Fail Predictably
Hallucination is when a model generates fluent, confident, factually incorrect text. It is not a bug that will be patched — it is a structural property of next-token prediction. The model is optimizing for plausible text, not verified facts.
Mitigation strategies exist. RAG grounds model outputs in retrieved documents. Output validation layers check generated text against known facts or structured schemas. Human-in-the-loop review is the backstop for high-stakes outputs.
Bias is the other structural issue. Training data reflects human biases — historical, cultural, demographic. Models inherit and sometimes amplify those biases in their outputs [SOURCE_4]. Operators building customer-facing systems have a responsibility to audit outputs and build containment layers before problems reach end users.
LLMs in Production: How Operators Are Building With Them
The gap between 'using ChatGPT manually' and 'deploying LLMs in production' is wide. Production deployment means reliability, observability, cost control, and error handling — not just generating good outputs in a demo.
Common production patterns in 2026 include RAG pipelines for knowledge-intensive tasks, agent frameworks for multi-step task completion, multi-model routing for cost and quality optimization, and structured output generation for downstream system integration. Orchestration frameworks exist because production LLM systems require more than a prompt and an API call — they require chains of operations, retrieval steps, validation logic, and fallback handling.
Evaluation does not stop at launch. Production systems need continuous monitoring of output quality, latency, and cost. The shift from 'AI experiment' to 'AI system' is the shift from asking 'does this work?' to asking 'does this work reliably, at scale, within budget?' [SOURCE_1] Learn more about AI Language Models Explained: How They Work.
LLM-Powered SEO and Content Automation: The Closed-Loop Use Case
Content and SEO is one of the highest-ROI application areas for LLM automation. The task volume is high, the structure is repeatable, and output quality is measurable — rankings and traffic are objective signals. That combination makes it a natural fit for closed-loop automation. Learn more about AI Language Models Explained: LLMs for Content Ops.
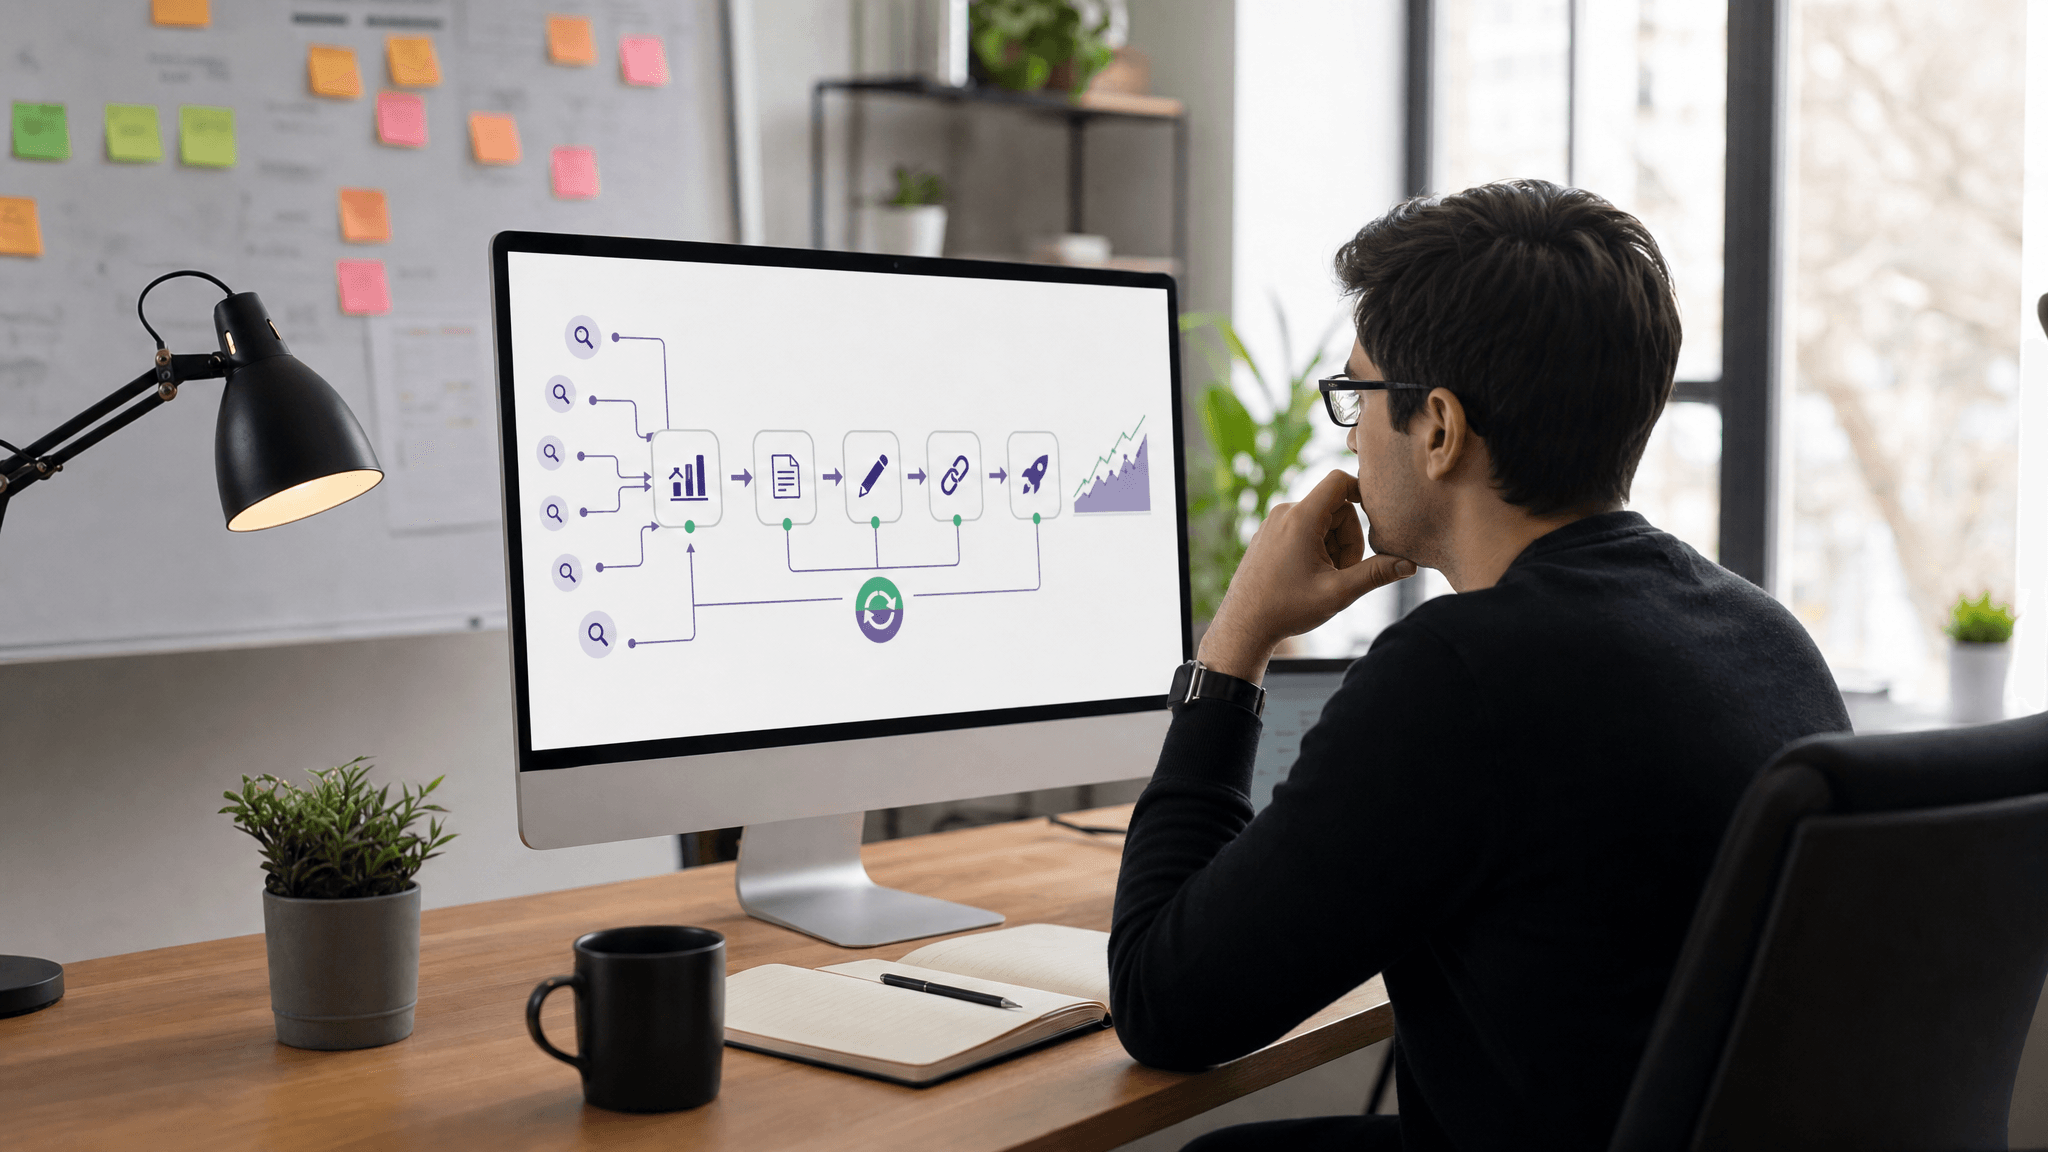
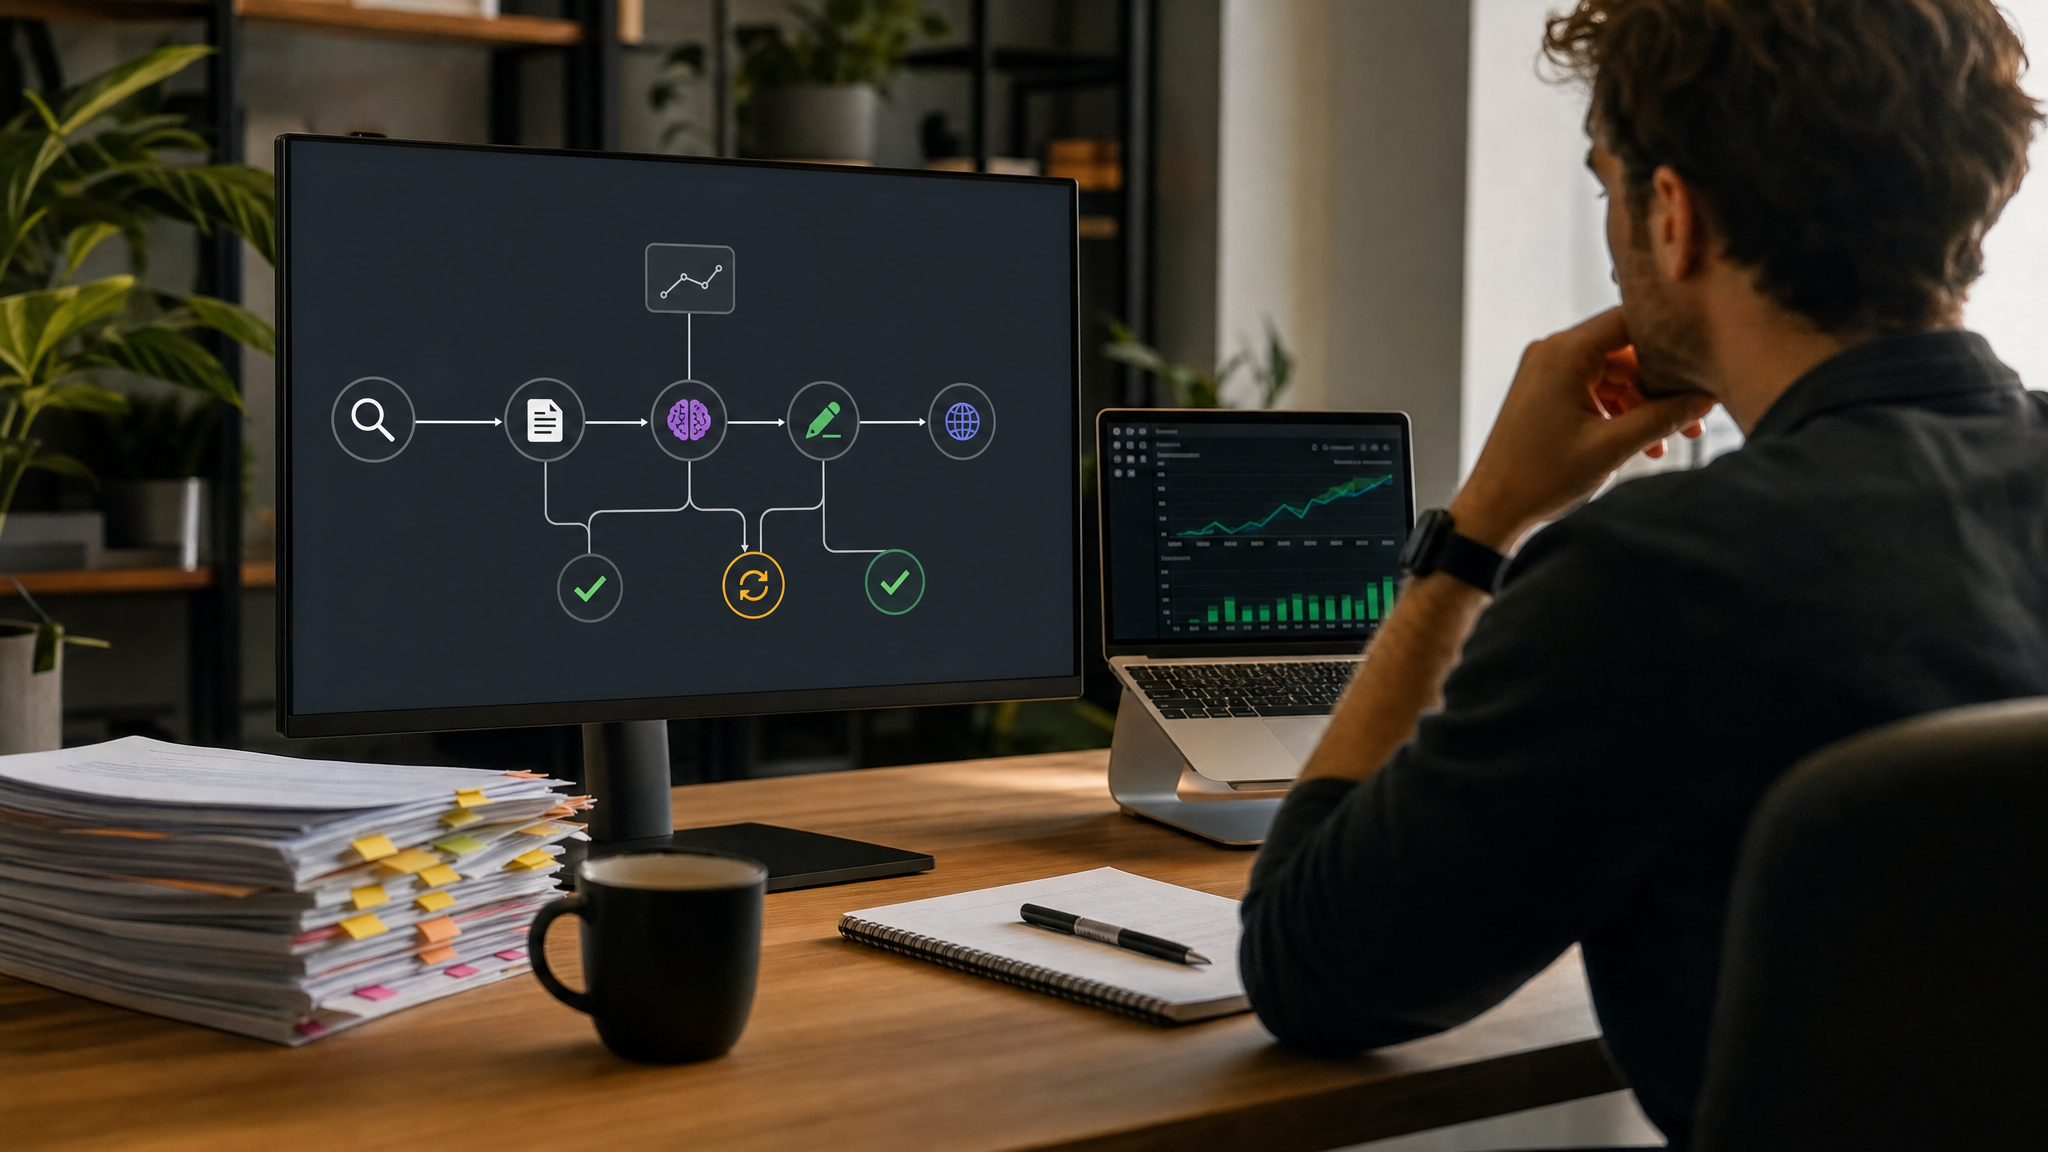
The difference between using ChatGPT manually and deploying an LLM in a closed-loop content system is fundamental. Manual use means a human is in the loop for every step: keyword research, briefing, writing, editing, publishing, monitoring. Closed-loop automation means the LLM handles discovery, generation, optimization, and republishing — the human sets the parameters, not the workflow. Learn more about Generative AI Chatbots 2026: Complete Guide + Top Tools.
Platforms like Ranklynk use LLMs as the intelligence layer in a fully autonomous SEO engine. The system handles keyword-to-publish workflows without a content team or agency. You stop babysitting the pipeline. The system runs. Learn more about Generative AI Chatbots 2026: Leaders & Content Stack.
The system-thinking shift here is important. Stop treating LLMs as writing assistants that help you work faster. Start treating them as automation infrastructure that removes the workflow entirely. Learn more about RAG Explained: How Retrieval-Augmented Generation Works.
Agentic LLMs: When Models Start Taking Actions
Agentic LLMs go beyond answering questions. They use tool-calling and multi-step reasoning to complete tasks autonomously. The model does not just generate text — it plans, takes actions, observes results, and adjusts. Learn more about AI Writing Assistant: Beyond Basic Tools in 2026.
Common agent patterns include ReAct (Reasoning + Acting), Plan-and-Execute, and multi-agent orchestration. Tool-calling lets agents trigger web searches, run code, query databases, and call external APIs — all within a single task loop. Learn more about AI Writing Assistant: When to Automate Beyond Writing.
Agentic architectures require more robust evaluation and error handling than single-turn inference. When a model takes a wrong action at step three of a ten-step chain, the error compounds. Operators building agentic systems need checkpoints, validation layers, and clear human escalation paths for high-stakes decisions. Learn more about Scale AI Content Production Without Sacrificing Quality.
How to Choose the Right AI Language Model: A Decision Framework
Choosing a model without a framework is how teams end up paying for GPT-4o on tasks that a much cheaper model handles equally well. Here is a practical decision process.
Step 1 — Define the task type. Is this a generation task, a reasoning task, a retrieval task, or a classification task? Different task types favor different model families.
Step 2 — Set your constraints. What is your cost budget per inference call? What latency is acceptable? Does your data need to stay on-premise? These constraints eliminate entire tiers of the model ecosystem before you evaluate quality.
Step 3 — Map to a starting model. Use this as a working reference:
- Long document summarization → Claude 3.5 (200K context, strong instruction-following)
- Code generation → GPT-4o or a specialized code model
- Semantic search and RAG retrieval → text-embedding-3-large or Cohere Embed
- High-volume content generation → Llama 3 70B self-hosted (cost control at scale)
- Multilingual tasks in regulated European markets → Mistral Large
- Multimodal tasks (text + image) → Gemini 1.5 Pro or GPT-4o
Step 4 — Evaluate on your actual task distribution. Run 50-100 representative examples through your shortlisted models. Score outputs on dimensions that matter for your use case — accuracy, format compliance, tone, factual grounding. Benchmark scores are a proxy, not a verdict.
Step 5 — Build for model-agnosticism. Abstract your model calls behind an interface layer so you can swap providers without rewriting your pipeline. The LLM market will keep shifting [SOURCE_4].
The Future of AI Language Models: What Operators Need to Track
Multimodality is becoming the standard, not a differentiator. In 2026, leading frontier models process text, images, audio, and in some cases video within a single context window. This expands the surface area of what LLM-powered systems can do.
Reasoning models separate the 'thinking' step from the 'output' step. The model reasons through a problem before generating a final response. This produces significantly better performance on complex multi-step tasks and reduces hallucination on tasks that require logical consistency.
On-device and edge LLMs are emerging as a parallel track. Smaller, distilled models running locally on phones and laptops eliminate the latency and privacy concerns of API calls.
The commoditization curve is the most important structural trend to track. Frontier model capabilities filter down to open-weight models within 12-18 months. The cost per unit of AI intelligence continues to fall. Capabilities that cost dollars per query in 2024 cost fractions of a cent per query in 2026 [SOURCE_3]. Operators who build cost-efficient, model-agnostic infrastructure now will benefit from that curve automatically.
Key Takeaways
AI language models are not a trend. They are the computational infrastructure of the next decade. Understanding the taxonomy — LLMs, transformers, GPT, fine-tuning, RAG — gives you the foundation to make better system design decisions. Understanding the ecosystem — frontier vs. open-weight, general vs. specialized — gives you the map to deploy the right model for the right task. Understanding production patterns — agents, routing, closed-loop pipelines — gives you the operational model for building systems that compound instead of experiments that stall.
The operators who win are not the ones who found the best prompt. They are the ones who built the tightest systems around the best models for their specific tasks.
If content and SEO is one of your highest-volume, most repeatable workflows, you do not need to hire a team or manage an agency to run it. See how Ranklynk's autonomous SEO engine uses LLMs as closed-loop infrastructure — handling discovery, generation, publishing, and optimization without you babysitting the pipeline. See how it works.
Frequently Asked Questions
Q: What is LLM and GPT?
LLM stands for Large Language Model — a type of AI language model trained on massive datasets of text to understand and generate human language using statistical pattern recognition. GPT stands for Generative Pre-trained Transformer, which is a specific architecture and product family developed by OpenAI. GPT models are a subset of LLMs, distinguished by their transformer-based architecture and pre-training approach. Think of it this way: LLM is the broad category, and GPT is a specific implementation within that category. Other LLMs include Claude (Anthropic), Gemini (Google), and Llama (Meta). All GPT models are LLMs, but not all LLMs are GPT models. In 2026, both terms are often used interchangeably in casual conversation, but understanding the distinction matters when making product or infrastructure decisions — especially when evaluating which model best fits a specific use case.
Q: What are the AI language models?
AI language models are statistical systems trained on large volumes of text data to predict, interpret, and generate human language. They work through a mechanism called next-token prediction — given existing text, the model calculates the most probable next word or token and repeats this process to produce coherent, contextually relevant output. Major AI language models available in 2026 include GPT-4o and o3 from OpenAI, Claude 3.5 and Claude 4 from Anthropic, Gemini 1.5 and 2.0 from Google DeepMind, Llama 3 from Meta, and Mistral from Mistral AI. These models power a wide range of applications including chatbots, writing assistants, coding tools, semantic search engines, and automated content pipelines. They are not retrieving stored answers — they are computing responses based on learned patterns, which is why output quality varies depending on how well you understand and structure your prompts.
Q: Is ChatGPT a language model?
ChatGPT is not itself a language model — it is a consumer application built on top of one. The underlying AI language model is GPT-4o (or whichever OpenAI model version is active), and ChatGPT is the product layer built around it. That product layer includes a conversational chat interface, safety and content filtering systems, memory features, usage controls, and additional fine-tuning for helpful dialogue. This distinction matters practically. When you interact with ChatGPT, you are interacting with a system that includes the raw model plus significant engineering around it. The same underlying model can behave differently depending on the system prompt, safety guardrails, and interface it is deployed within. Understanding this separation helps builders make smarter decisions — because accessing the model directly via API gives you far more control than using the consumer ChatGPT interface.
Q: What is the best AI language model?
There is no single best AI language model in 2026 — the right choice depends entirely on your use case, budget, latency requirements, and integration needs. That said, here is how the top contenders break down: OpenAI's GPT-4o and o3 models excel at general-purpose reasoning, coding, and content generation. Anthropic's Claude models are widely regarded as strong performers for long-context tasks and nuanced writing. Google's Gemini 2.0 offers deep integration with Google Search and Workspace products, making it powerful for research-heavy workflows. Meta's Llama 3 is the leading open-source option, ideal for teams that need on-premise deployment or cost control. For content and SEO workflows specifically, models that balance speed, cost, and output quality at scale — like GPT-4o mini or Claude Haiku — often outperform flagship models when factoring in total operational cost. Benchmark scores matter less than real-world performance on your specific tasks.
Q: Is ChatGPT an LLM or generative AI?
ChatGPT is both — but with an important distinction. It is a generative AI application that is powered by an LLM (Large Language Model). The LLM, specifically OpenAI's GPT architecture, is the core AI language model doing the computational work of predicting and generating text. Generative AI is the broader category that describes AI systems capable of producing new content — text, images, audio, video, or code. ChatGPT falls into the generative AI category because it generates novel text responses rather than retrieving pre-written answers. So the accurate framing is: ChatGPT is a generative AI product built on an LLM foundation. This distinction is useful when evaluating tools because it clarifies where the real capability lies — in the underlying model — and why different applications built on the same model can produce meaningfully different results based on how they are engineered.
Q: Why are people leaving ChatGPT?
In 2026, users and builders are diversifying away from ChatGPT for several reasons. First, increased competition has produced genuinely strong alternatives. Anthropic's Claude models have earned a reputation for better long-form reasoning and fewer refusals. Google's Gemini offers native integration with Workspace and real-time web access. Second, cost is a factor — for teams running high-volume AI workflows, API access to competing models is often cheaper than OpenAI's pricing tiers. Third, some advanced users find ChatGPT's consumer-facing safety layers too restrictive for technical or professional use cases. Fourth, open-source models like Meta's Llama 3 allow organizations to run AI language models on their own infrastructure, eliminating data privacy concerns entirely. Finally, builders increasingly want best-in-class models for specific tasks rather than a single general-purpose tool. The shift is less about leaving ChatGPT and more about adopting a multi-model strategy.
Q: What are the top 5 most popular AI models?
As of 2026, the most widely used and referenced AI language models are: 1) GPT-4o (OpenAI) — the dominant general-purpose model powering ChatGPT and widely used via API across thousands of applications. 2) Claude 3.5 / Claude 4 (Anthropic) — increasingly popular for enterprise use cases requiring strong reasoning, long context windows, and reliable output quality. 3) Gemini 2.0 (Google DeepMind) — integrated across Google's product suite and favored for research and real-time information tasks. 4) Llama 3 (Meta) — the leading open-source AI language model, preferred by developers and organizations that need self-hosted or customizable deployments. 5) Mistral Large (Mistral AI) — a European-origin model gaining traction for its efficiency and strong multilingual capabilities. Each model has distinct strengths, pricing structures, and integration ecosystems. Most serious operators in 2026 use more than one, routing different tasks to the model best suited for the job.